

MII makes low-latency and high-throughput inference possible, powered by DeepSpeed.
Open source
24 alternativesBanana hosts GPUs for AI inference and supports autoscaling for high-throughput workloads.
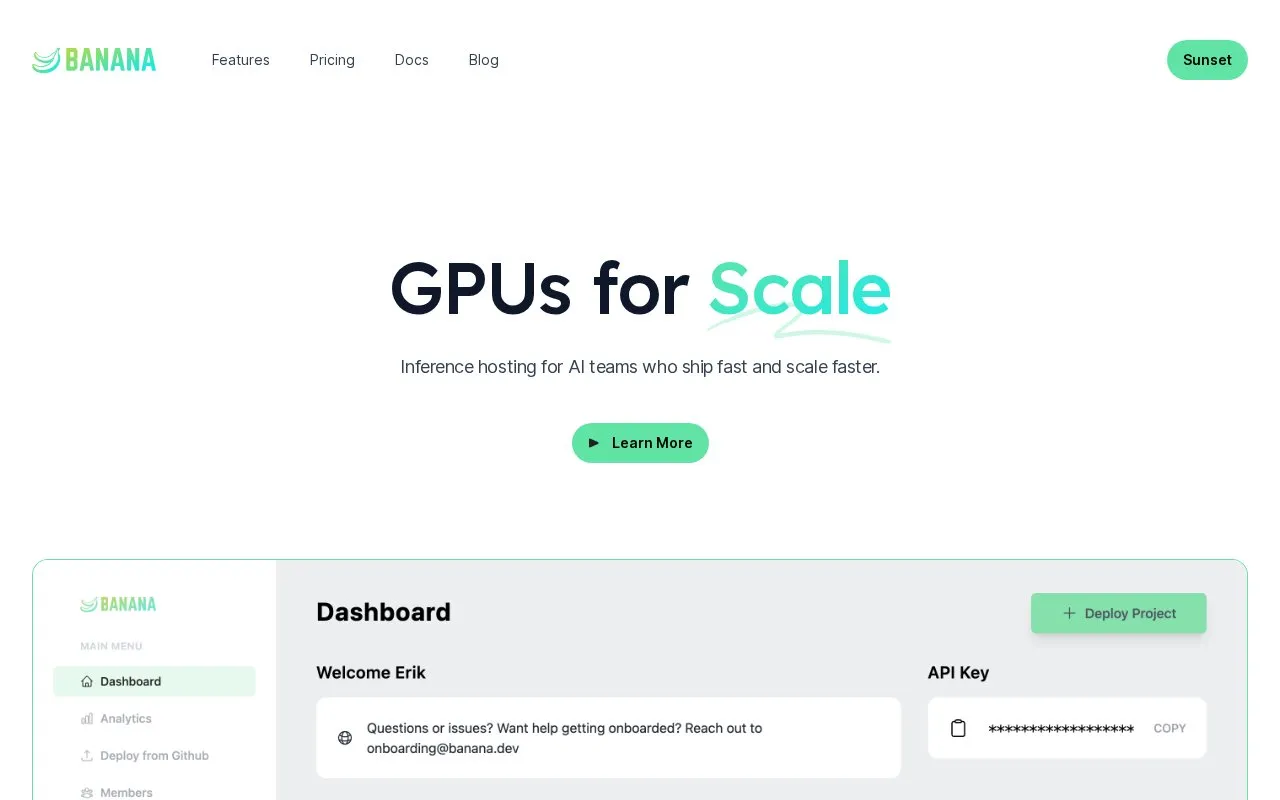
Banana is a hosted inference service that provides GPUs for running AI models. Its homepage describes it as built for high-throughput inference, with GPU capacity that scales up and down automatically with demand. The platform includes built-in observability for request traffic, latency, errors and logs, along with spend and endpoint usage tracking over time.
Developers can deploy and manage workloads through GitHub integration, CI/CD, a CLI, rolling deploys and an open API with SDKs. The homepage describes its pricing as a flat monthly rate plus the cost of compute. Plan details, such as member, project and GPU limits, are listed by plan and some features appear only on the Enterprise plan. A separate banana delivery offer is listed for San Francisco only. Current pricing is not confirmed in this entry.
Tools and sites you could use instead, ranked by how closely they match.
MII makes low-latency and high-throughput inference possible, powered by DeepSpeed.
Runpod provides on-demand GPUs and serverless compute for AI model training, fine-tuning, inference, and batch workloads.
Wallaroo provides inference microservices for running models on CPUs or GPUs across cloud and edge environments.
Run sandboxes, task queues, and custom model inference with ultrafast boot times, instant autoscaling, and a developer experience that just works.
Forefront provides a platform for fine tuning and running inference with open source language models.
Featherless is a serverless AI inference platform for open-weight models with API access to tens of thousands of models.
Well-known listings from the same topic.
Tell us and an editor will check it.
Claim the listing and suggest updates yourself. An editor checks every claim first.


