

AudioCraft provides research code for generating music and sound effects and for audio compression.
CassetteAI
CassetteAI provides music, sound-effect, and text-to-speech models through an SDK designed to run on edge hardware.
About CassetteAI
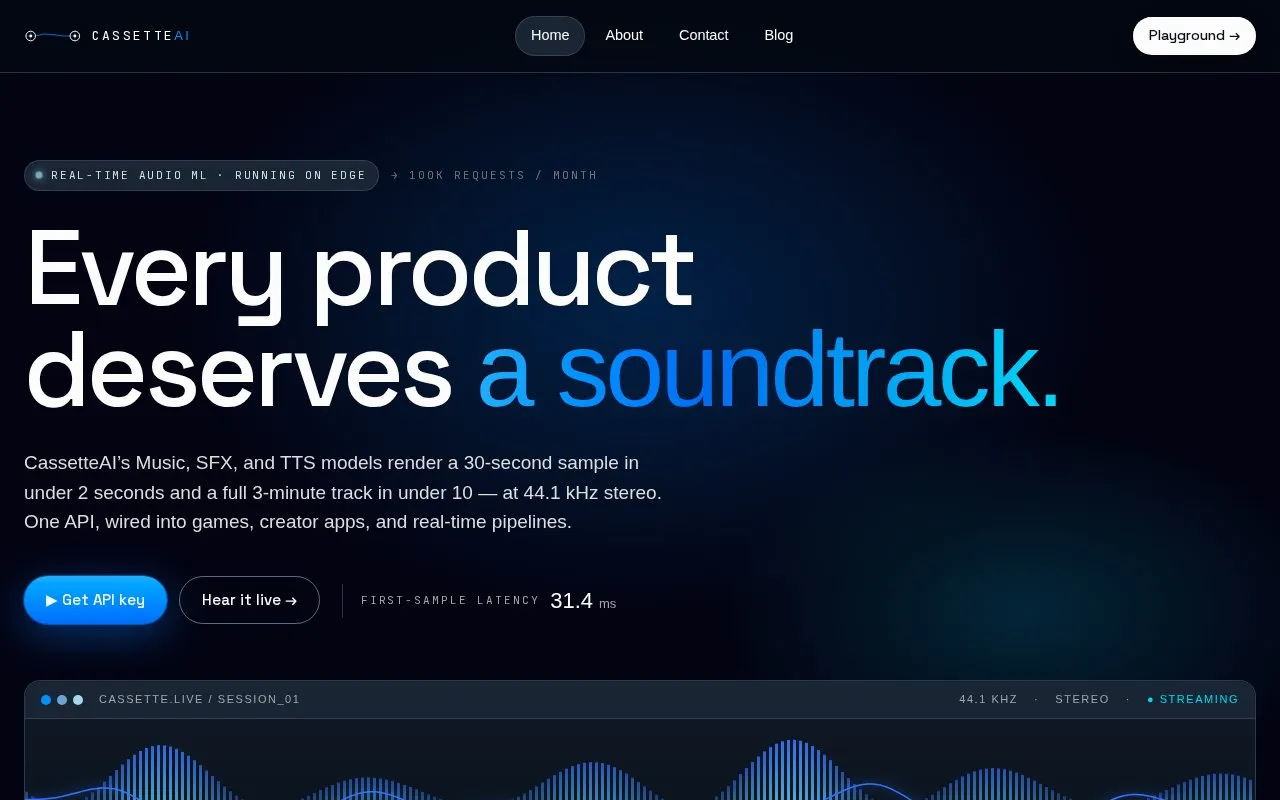
CassetteAI provides music, sound-effect, and text-to-speech models through an SDK designed to run on edge hardware. Music is generated from prompts for mood, genre, tempo, or key, with a 30-second sample in under 2 seconds and a 3-minute track in under 10 seconds at 44.1 kHz stereo. Sound effects are generated from text descriptions in durations of 1 to 30 seconds.
Developers access the models with a shared API shape from JavaScript, Python, or cURL. A live playground with presets allows testing music and SFX without signup. Text-to-speech with zero-shot cloning from a 10-second sample and emotion tags is listed as launching soon.
Key features
- Generate music tracks from prompts for mood, genre, tempo, key
- Generate sound effects up to 30 seconds from text descriptions
- Output 44.1 kHz stereo 16-bit .wav files
- Use deterministic seeds for repeatable music and SFX outputs
- Access music and SFX through same API call shape
- Test music and SFX in live playground with presets
Best for: Developers building games, creator apps, and real-time pipelines that need generated music and sound effects.
Good for
- Single API shape for music and sound-effects models
- 44.1 kHz stereo .wav output
- Live playground allows testing without signup
Watch out for
- Text-to-speech model is listed as launching soon
CassetteAI at a glance
- Website
- cassetteai.com
- Category
- AI & Machine Learning › AI Voice & Audio
- Type
- Online tool
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
CassetteAI alternatives
Tools and sites you could use instead, ranked by how closely they match.

OptimizerAI generates sound effects from text prompts for creators, game developers, and video makers.

Sound Effect AI generates original sound effects for audio production instead of extracting effects from existing videos.
Paid
6 alternatives
Cloudglue provides APIs that turn video into context for AI, including speech, speaker diarization, visual descriptions, and sound data.

StockmusicGPT generates royalty-free stock music, sound effects, and song covers with an AI composition tool.

The Kokoro-82M model provides open-weight text-to-speech with 82 million parameters.
Popular in AI Voice & Audio
Well-known listings from the same topic.
Google Illuminateilluminate.google.comAlteredaltered.aiELSA Speakelsaspeak.comKreadoAIkreadoai.comPodwisepodwise.aiAddsubtitleaddsubtitle.ai


CassetteAI FAQ
How long does generation take?
A 30-second music sample renders in under 2 seconds and a 3-minute track in under 10 seconds; a sound effect up to 30 seconds renders in roughly 1 second.
What output format is provided?
44.1 kHz stereo 16-bit .wav.
Is the text-to-speech model available?
No, it is listed as launching soon.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.