
Groq provides cloud infrastructure and developer APIs for running AI model inference.
deepseek-v4-flash
DeepSeek’s API documentation lists pricing and capabilities for its DeepSeek-V4-Flash model.
About deepseek-v4-flash
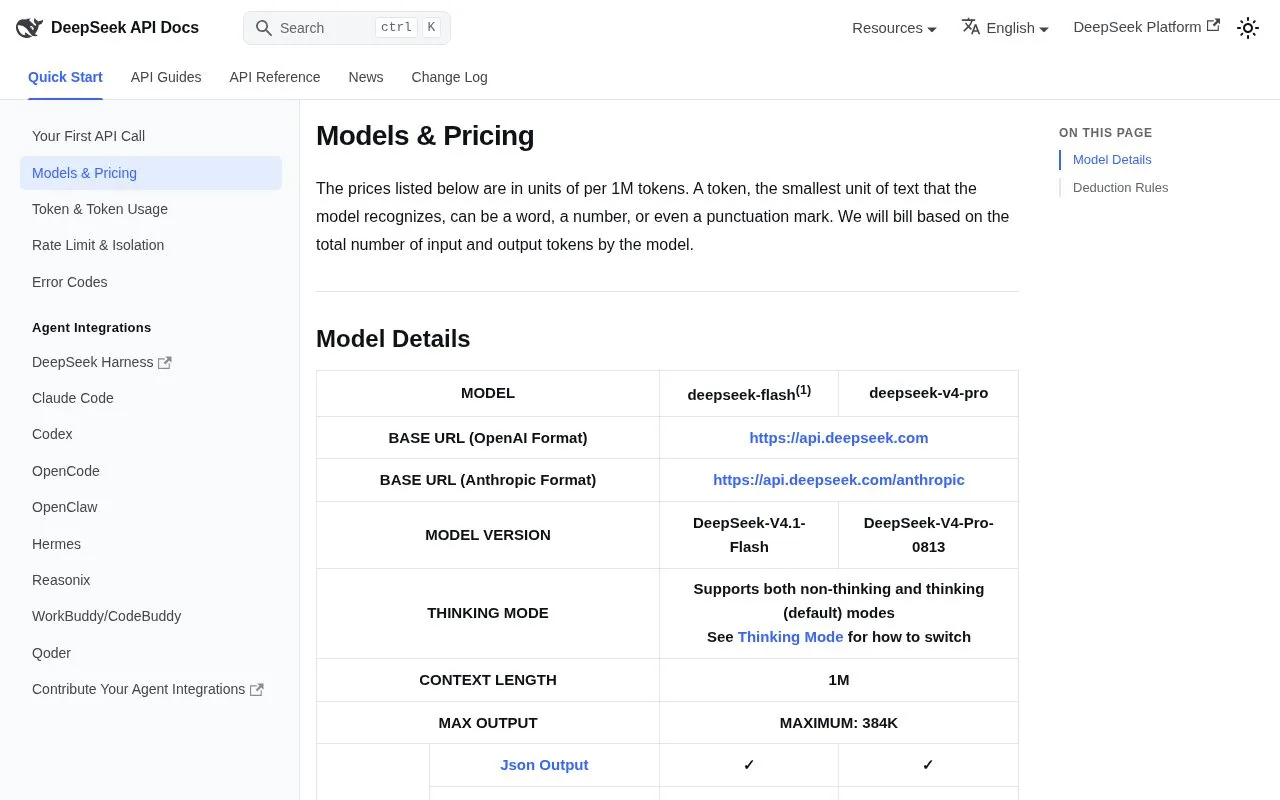
This entry describes DeepSeek's API documentation page for its Flash model, which lists model details and per-token pricing. The page gives the model name as deepseek-flash. The name deepseek-v4-flash is still accepted, but the page says those legacy models have been retired and their requests are served by DeepSeek-V4.1-Flash at the Flash price.
The model supports a context length of 1M tokens and a maximum output of up to 384K tokens. It offers both non-thinking and thinking modes, with thinking as the default. Listed features include JSON output, tool calls, the Responses API, the Anthropic API format, and vision input. Chat prefix completion and FIM completion are in beta, and FIM completion works only in non-thinking mode. Prices are listed per 1M input or output tokens. Off-peak rates are half of peak rates, and cache-hit input prices are lower than cache-miss prices. Prices may change, and the page recommends checking it for current rates.
Key features
- Context length of 1M tokens
- Maximum output of up to 384K tokens
- Non-thinking and thinking modes, with thinking as default
- JSON output and tool calls supported
- Vision input supported on this model
- Chat prefix completion and FIM completion in beta
Best for: Developers building applications on the DeepSeek API who need long context, tool calls, or structured JSON output and want to track token-based costs.
Good for
- Off-peak token rates are half of peak rates
- Cache-hit input prices are lower than cache-miss input prices
- Supports a context length of 1M tokens
Watch out for
- Prices may change, and DeepSeek reserves the right to adjust them
- FIM completion is available only in non-thinking mode
- Legacy model names are retired and map to DeepSeek-V4.1-Flash
deepseek-v4-flash at a glance
- Type
- Online tool
- Pricing
- Paid
- Platforms
- Web
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
deepseek-v4-flash alternatives
Tools and sites you could use instead, ranked by how closely they match.

Baidu Qianfan lists pricing and capabilities for models and services on the Baidu AI Cloud platform.

Z.AI’s developer documentation explains how to access its models and services through an API.
Freemium
24 alternatives
GPU Per Hour compares live cloud GPU prices across providers and hardware types.

NVIDIA NIM offers APIs for trying models used to build enterprise generative AI applications.

Forefront provides a platform for fine tuning and running inference with open source language models.
Freemium
24 alternativesPopular in AI Infrastructure & MLOps
Well-known listings from the same topic.
Guild AIguild.aiFlow AIflow-ai.comsystemprompt.iosystemprompt.ioCoreWeavecoreweave.comKili Technologykili-technology.comAPI docsdocs.x.ai


deepseek-v4-flash FAQ
When are peak hours for pricing?
Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday, excluding Chinese public holidays. All other hours are off-peak, including weekends and Chinese public holidays in full.
How is usage billed?
The expense equals the number of tokens multiplied by the price. Fees are deducted from the topped-up balance or the granted balance, with the granted balance used first when both are available.
Which model name should be used?
The page says to use deepseek-flash as the model name. The legacy names deepseek-v4-flash and deepseek-v4-flash-vision-exp are still accepted, but those models have been retired and their requests are served by DeepSeek-V4.1-Flash.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.