
Petals runs large language models at home through a BitTorrent-style approach and supports text generation and fine-tuning.
Petals
Petals runs large language models across distributed computers and supports fine-tuning and inference.
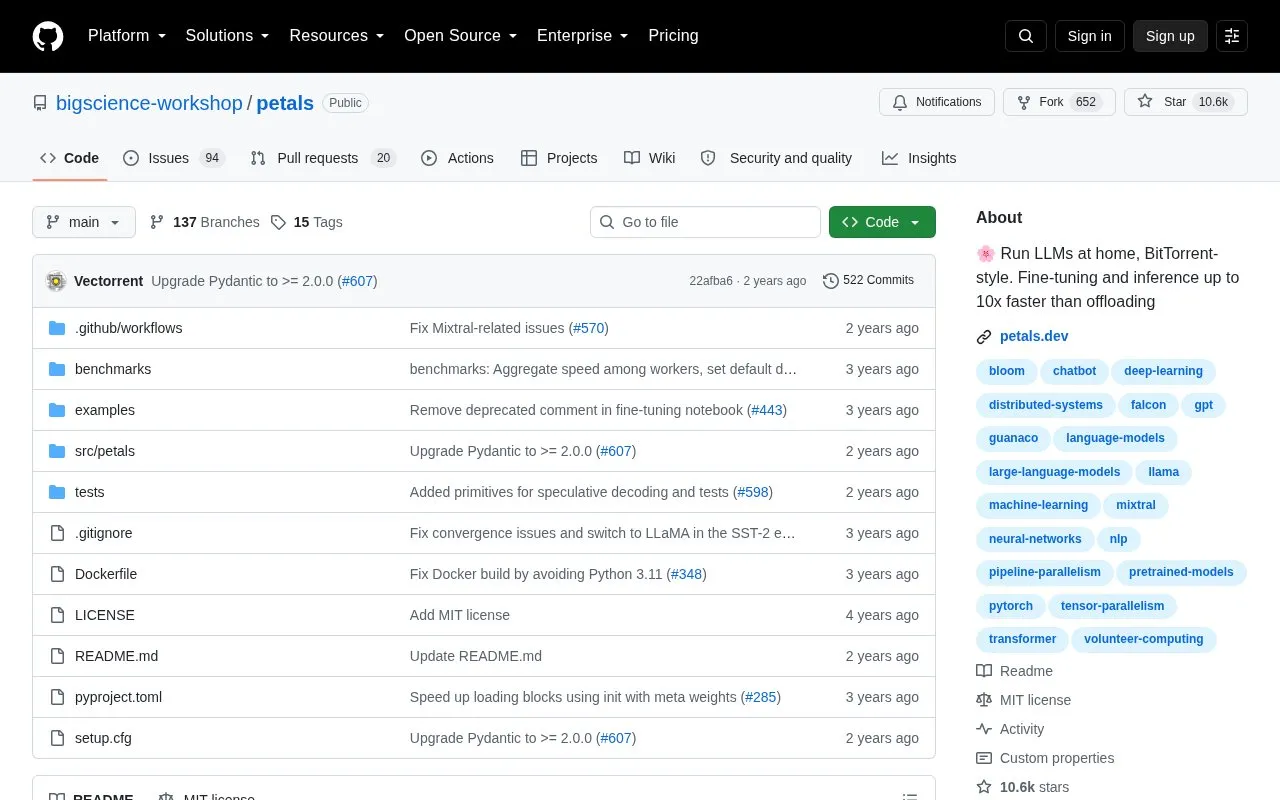
About Petals
Petals is an open-source repository that enables running large language models across distributed, community-hosted networks, removing the need to store full model weights on a single local device. It supports both inference and fine-tuning for models including Llama 3.1 (up to 405B parameters), Mixtral (8x22B), Falcon (40B+), and BLOOM (176B). The system splits model layers across participating devices in either public or private swarms, with claimed performance up to 10x faster than standard offloading for fine-tuning and inference. Cited example throughput reaches up to 6 tokens per second for Llama 2 70B and 4 tokens per second for Falcon 180B, sufficient for interactive chatbots and similar applications.
Key features
- Distributed BitTorrent-style LLM hosting across community devices
- Supports fine-tuning and inference for large open-source LLMs
- Compatible with Llama 3.1, Mixtral, Falcon, and BLOOM models
- Integrates with PyTorch and Hugging Face Transformers APIs
- Supports both public community and private trusted swarm configurations
- Includes chatbot web app and public swarm monitoring tools
Best for: It benefits users seeking to run large LLMs on consumer hardware without local full model storage, as well as users willing to share GPU resources for distributed model hosting.
Good for
- Eliminates need for high-end local hardware to run 400B+ parameter LLMs
- Claims up to 10x faster fine-tuning and inference than standard offloading
- Supports both public community swarms and private trusted swarms for sensitive use cases
Watch out for
- Public swarm data is processed by other network participants, posing privacy risks for sensitive information
- Inference speed depends on swarm performance, with max cited throughput of 6 tokens/sec for Llama 2 70B
- Hosting model layers requires a compatible GPU and supported operating system setup
Petals at a glance
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Open source
- Yes · Source code
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
Petals alternatives
Tools and sites you could use instead, ranked by how closely they match.

LLM-API-Key-Proxy provides a gateway for multiple language model APIs, with compatible endpoints and provider translation.

This bilingual chat language model is described in English and Chinese on the ChatGLM2-6B repository page.

LocalAI runs text, voice, vision, image, video, and agent workloads through an open-source AI engine.
Open source
24 alternatives
Jan runs an offline AI chat assistant on a personal computer as an open-source ChatGPT alternative.
Open source
24 alternatives
GPT4All runs language models locally on a range of devices through open-source software.
Open source
24 alternativesPopular in AI Chatbots & Assistants
Well-known listings from the same topic.
Lumolumo.proton.meMicrosoft Copilotcopilot.microsoft.comLearn Aboutlearning.google.com/experiments/learn-aboutEidoloneidolonai.comFlowHuntflowhunt.ioPine AI19pine.ai


Petals FAQ
How does Petals enable running large LLMs without local full model storage?
It splits model layers across a distributed network of participating devices, so users only host a small portion of the model locally.
Is Petals suitable for processing sensitive data?
Sensitive data can be used with a private swarm of trusted participants; public swarm data is processed by other network users.
What hardware and systems are required to host Petals model layers?
Hosting requires a compatible NVIDIA, AMD, or Apple M1/M2 GPU, with support for Linux, Windows WSL, macOS, or Docker environments.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.