

Fiddler provides evaluation, monitoring, enforcement, governance, and cost controls for enterprise AI agents.
Ragas
Ragas provides an evaluation framework for AI applications, according to its documentation page.
About Ragas
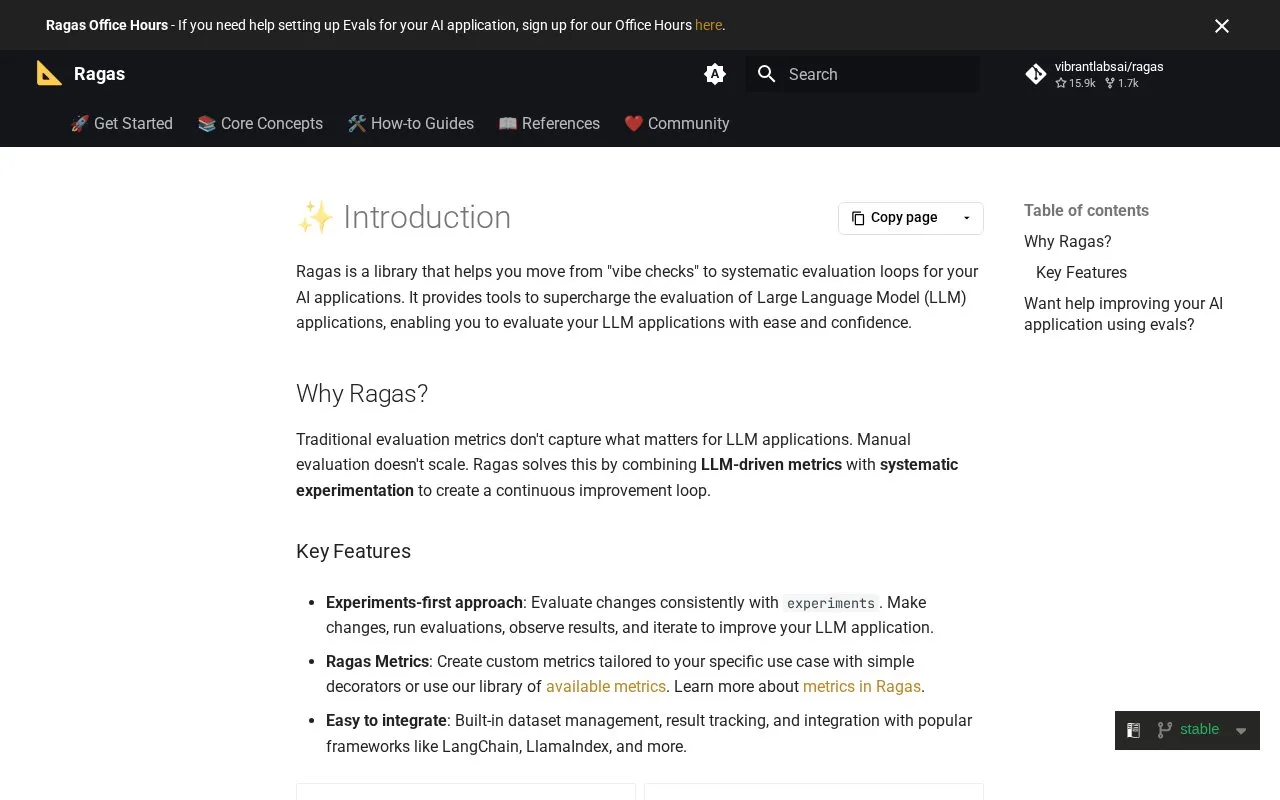
Ragas is a library for evaluating Large Language Model (LLM) applications. Its homepage describes it as a way to move from informal "vibe checks" to systematic evaluation loops. It combines LLM-driven metrics with experiments, so that changes to an application can be tested, measured, and compared over time.
The library provides metrics for scoring application outputs, dataset management, and result tracking. Its homepage also lists integrations with frameworks such as LangChain and LlamaIndex. Pricing is not stated on the homepage.
Key features
- Experiments-first workflow for making, running, and comparing changes to an LLM application
- Custom metrics created with simple decorators
- Library of prebuilt evaluation metrics
- Built-in dataset management and result tracking
- Integration with frameworks such as LangChain and LlamaIndex
Best for: Teams building LLM applications that need repeatable, systematic evaluation of changes rather than manual checks.
Good for
- Uses experiments to evaluate changes in a consistent way
- Supports both custom metrics and a library of existing metrics
- Includes dataset management and result tracking in the library
Ragas at a glance
- Website
- docs.ragas.io/en/stable
- Category
- AI & Machine Learning › AI Data & Analytics
- Type
- Online tool
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
Ragas alternatives
Tools and sites you could use instead, ranked by how closely they match.

Uncover LLM evaluation's importance and explore methods for assessing its performance and impact across industries.

Research on evaluation of LLMs conducted by Microsoft Research and other collaborated institutes. (Updated at: 2023/10).

This guide explains LLM evaluation metrics, including measures for retrieval augmented generation and agents, with DeepEval examples.

Evals is a framework for evaluating LLMs and LLM systems, and an open-source registry of benchmarks.
Open source
24 alternatives
LLMeBench provides a flexible framework for benchmarking large language models.
Popular in AI Data & Analytics
Well-known listings from the same topic.
Dotgetdot.aiForvioforvio.comFluidAI Medicalfluidai.mdApache Zeppelinzeppelin.apache.orgSola Securitysola.securityQuadraticquadratichq.com


Ragas FAQ
Can I get help setting up evaluations with Ragas?
The homepage mentions office hours for help setting up evals for an AI application, and a way to book a slot for help improving an application using evals.
Which frameworks does Ragas integrate with?
The homepage names LangChain and LlamaIndex as examples of popular frameworks it integrates with, and says there are more.
How are custom metrics created in Ragas?
According to the homepage, custom metrics can be created with simple decorators, or you can use the library of available metrics.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.