

UnDatasIO transforms unstructured documents into data assets for AI applications, including document parsing.
Webcrawler API
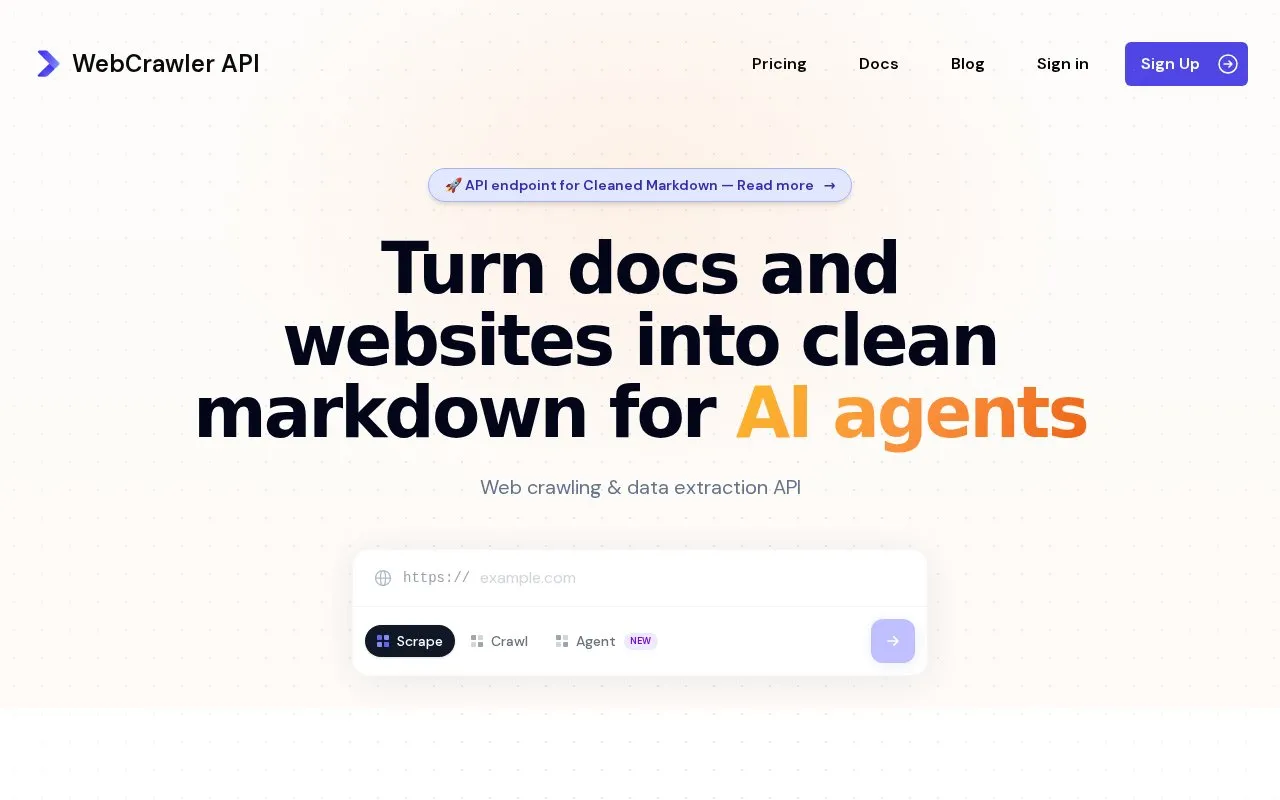
Webcrawler API crawls websites, documentation and help centers into markdown for AI support agents, with JavaScript and CAPTCHA handling.
About Webcrawler API
Webcrawler API is a hosted web crawling and data extraction service that turns pages from websites, documentation and help centers into cleaned markdown for AI support agents and knowledge products. It loads a page, removes menus, cookie banners, footers and ads, and returns formatted markdown intended for use in prompts, indexing or storage.
The service handles JavaScript rendering, CAPTCHAs, anti-bot protection, residential proxies, automatic retries and rate limit handling on its side. It offers smart caching for frequently requested pages and change-detection feeds that report changed pages, new additions, removals and diffs. Crawling is driven through a REST API, with code examples for several languages and documented no-code integrations.
Key features
- Cleaned markdown extraction that removes menus, cookie banners, footers and ads
- Handles JavaScript rendering, CAPTCHAs, anti-bot protection, residential proxies and automatic retries
- Smart caching returns frequently requested pages in about 0.9 seconds
- Change detection feeds report changed pages, new additions, removals and diffs
- No-code integrations documented for Zapier, Make, n8n and Integrately
- Crawl endpoint with examples in cURL, Node.js, Python, PHP and Java
Best for: Developers and AI teams building support bots or knowledge products that need site content delivered as clean, ready-to-use markdown.
Good for
- Handles JavaScript rendering, CAPTCHAs and proxies so users do not manage scraping infrastructure
- Published pricing includes pay-as-you-go and monthly plans, with charges listed only for successful requests
- No-code guides are provided for Zapier, Make, n8n and Integrately
Watch out for
- Not open source; the documented setup requires an API key for the hosted service
- Charges are per page, with a higher listed rate for LLM-cleaned markdown
- Performance and reliability figures on the site are its own reported metrics
Webcrawler API at a glance
- Website
- webcrawlerapi.com
- Type
- Online tool
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
Webcrawler API alternatives
Tools and sites you could use instead, ranked by how closely they match.

Firecrawl provides a web data API for searching, scraping, and accessing information from web sources.
Open source
24 alternatives
LlamaIndex processes documents for AI applications and provides developer documentation and integrations.
Open source
24 alternatives
Flow AI provides data-agent infrastructure with a catalog and typed plans for building analytical agents over data products.

LiteLLM provides a way to call more than 100 language models through an OpenAI-compatible interface.

Fiber presents a simple approach to distributed computing for AI workloads.
Popular in AI Infrastructure & MLOps
Well-known listings from the same topic.
Guild AIguild.aisystemprompt.iosystemprompt.ioKili Technologykili-technology.comAPI docsdocs.x.aiEyePop.aieyepop.aiWeco Observeweco.ai


Webcrawler API FAQ
How fast are cached pages returned?
Frequently requested pages are returned from the smart cache in about 0.9 seconds instead of 4.7 seconds, and max_age=0 bypasses the cache.
Do I pay for failed requests?
The listed plans state pay only for successful requests.
Can the service be used without writing code?
Guides cover no-code connections with Zapier, Make, n8n and Integrately.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.