

LLMeBench provides a flexible framework for benchmarking large language models.
OpenLM Arena
OpenLM Arena compares open language models through leaderboards and benchmark results.
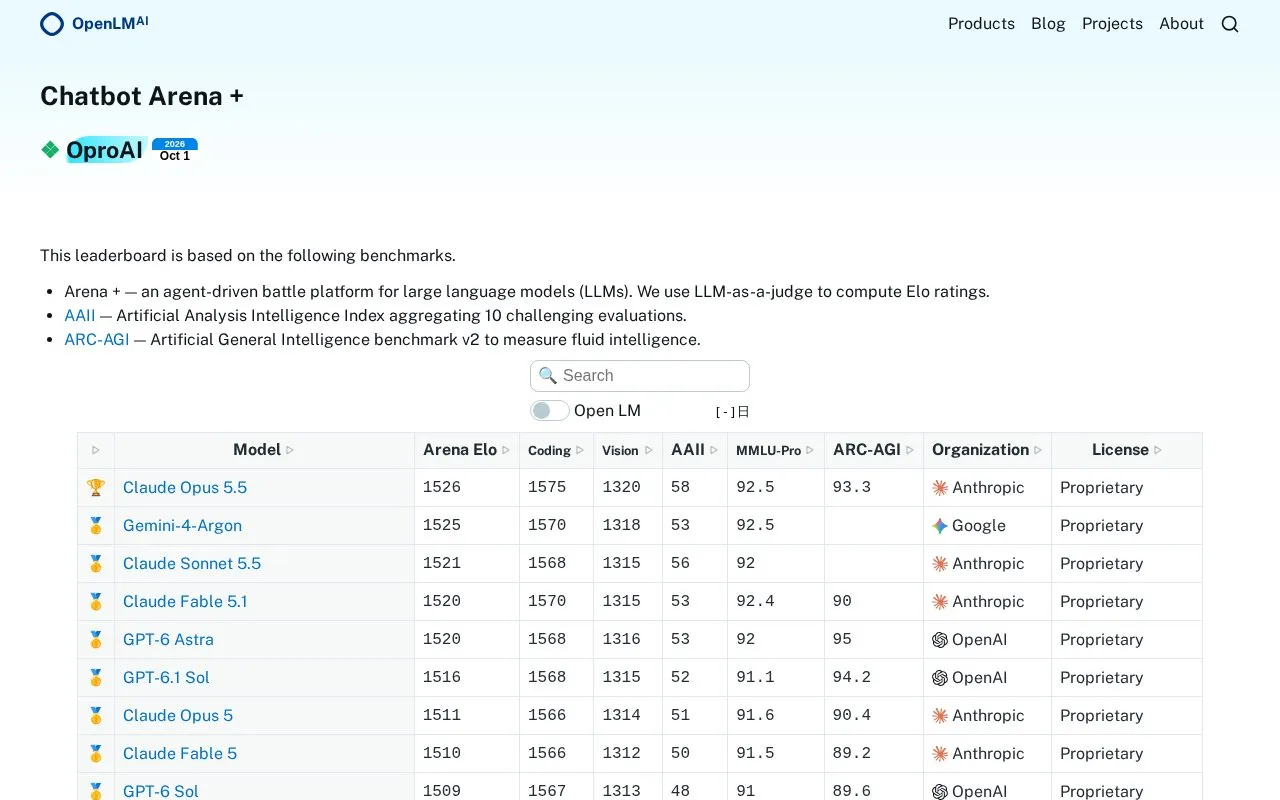
About OpenLM Arena
OpenLM Arena is a web-based platform that compares large language models (LLMs) through leaderboards and benchmark results. It operates an agent-driven battle platform where LLMs compete in head-to-head matchups, using an LLM-as-a-judge system to compute Elo ratings for each model. The platform also aggregates scores from multiple standardized evaluations, including the 10-challenge AAII benchmark, ARC-AGI v2 for fluid intelligence measurement, MMLU-Pro, and coding and vision tests, to provide additional context for model performance comparisons.
Key features
- Agent-driven LLM battle platform for head-to-head comparisons
- LLM-as-a-judge system to compute Elo ratings
- Leaderboard ranking models by Elo and benchmark scores
- Aggregated scores from 10-challenge AAII benchmark
- ARC-AGI v2 benchmark scores for fluid intelligence measurement
- Displays model license, organization, and multi-benchmark results
Best for: The platform is best for users seeking to compare the performance of different large language models using standardized benchmarks and head-to-head battle results.
Good for
- Uses LLM-as-a-judge for Elo ratings from head-to-head model battles
- Aggregates multiple challenging benchmarks for comprehensive model comparison
- Includes clear model metadata such as organization and license type
OpenLM Arena at a glance
- Website
- openlm.ai/chatbot-arena
- Category
- AI & Machine Learning › AI Data & Analytics
- Type
- Website
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
OpenLM Arena alternatives
Tools and sites you could use instead, ranked by how closely they match.

Uncover LLM evaluation's importance and explore methods for assessing its performance and impact across industries.

The Hugging Face Open LLM Leaderboard compares language models across evaluation tests including IFEval, MATH, and MMLU-Pro.

Aider LLM Leaderboards compares language models on code editing benchmarks.

SpeechMap.AI compares language models’ refusal rates on controversial speech topics.
Context Arena provides a leaderboard for evaluating language models on long-context tasks.
Popular in AI Data & Analytics
Well-known listings from the same topic.
Dotgetdot.aiForvioforvio.comFluidAI Medicalfluidai.mdApache Zeppelinzeppelin.apache.orgSola Securitysola.securityQuadraticquadratichq.com


OpenLM Arena FAQ
How are model rankings calculated on OpenLM Arena?
Rankings are based on Elo ratings from agent-driven LLM battles, plus aggregated scores from benchmarks including AAII, ARC-AGI, MMLU-Pro, coding and vision tests.
What benchmarks are used to evaluate models on the platform?
Evaluations include the 10-challenge AAII benchmark, ARC-AGI v2 for fluid intelligence, MMLU-Pro, coding and vision benchmarks.
What metadata is provided for each listed model?
Each model entry includes its organization, license type, and scores across all supported benchmarks.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.