
ccusage analyzes token usage and estimated costs for coding agent command-line tools.
SEAL LLM Leaderboard
Explore leaderboards with expert-driven LLM benchmarks and updated AI model rankings across coding, reasoning and more.
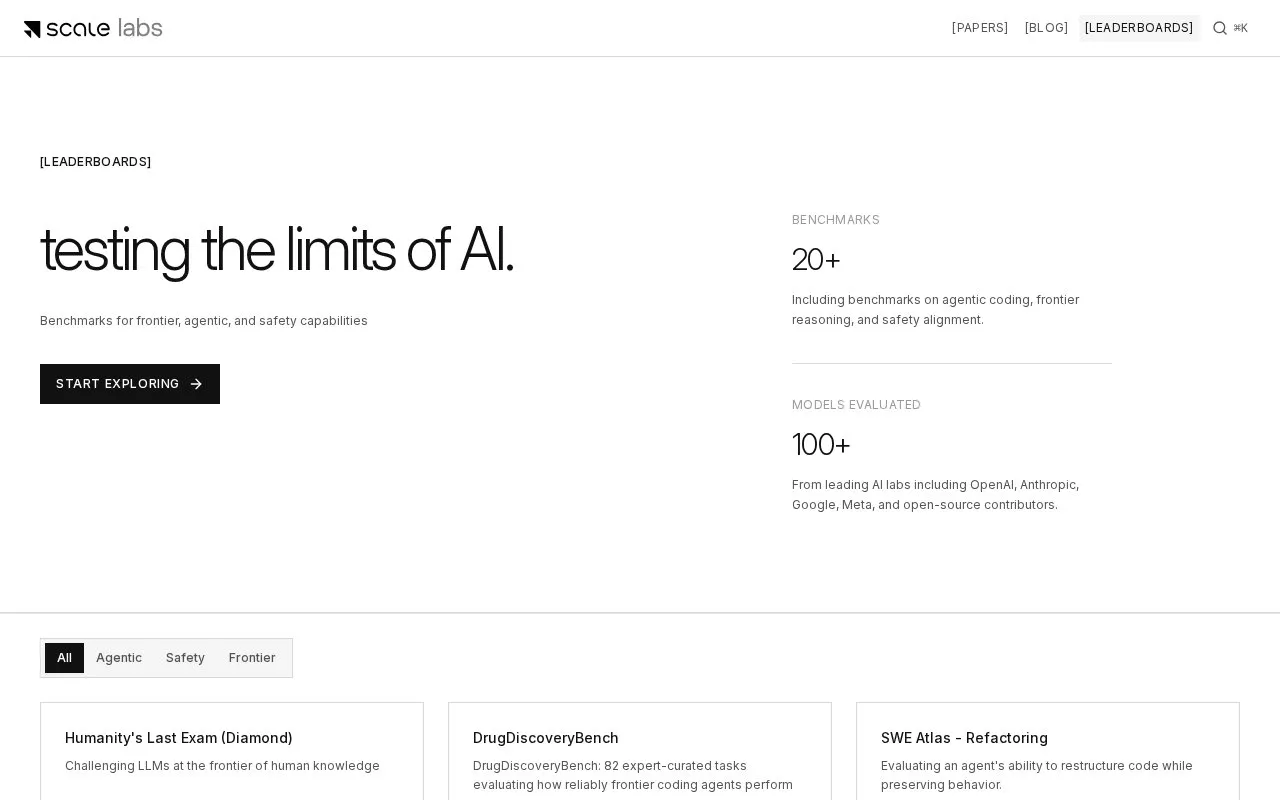
About SEAL LLM Leaderboard
The SEAL LLM Leaderboard is a web-based platform from Scale Labs that hosts expert-curated benchmarks and updated rankings for large language models (LLMs). It evaluates models across a broad set of capabilities, including agentic coding, frontier reasoning, safety alignment, professional domain performance, and multimodal tasks.
The platform includes more than 20 distinct benchmarks and has evaluated over 100 models from leading AI labs such as OpenAI, Anthropic, Google, and Meta, as well as open-source contributors. All rankings are presented alongside performance scores and associated confidence intervals.
Key features
- Over 20 expert-curated LLM benchmarks across diverse capability areas
- Rankings for 100+ LLMs from leading AI labs and open-source projects
- Benchmarks covering agentic coding, reasoning, safety, and professional domains
- Performance scores with confidence intervals for all model rankings
- Specialized benchmarks for crisis support, drug discovery, and tool use
- Multimodal and multilingual LLM evaluation benchmarks included
Best for: The platform is most useful for AI researchers, developers, and organizations that need to compare LLM performance across standardized, expert-reviewed benchmarks.
Good for
- Covers a wide range of specialized and general LLM evaluation capabilities
- Includes benchmarks developed in partnership with external organizations
- Provides transparent performance metrics with confidence intervals for all rankings
SEAL LLM Leaderboard at a glance
- Website
- labs.scale.com/leaderboard
- Category
- AI & Machine Learning › AI Data & Analytics
- Type
- Website
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
SEAL LLM Leaderboard alternatives
Tools and sites you could use instead, ranked by how closely they match.

DeepSWE benchmarks coding agents on long-horizon software engineering tasks and publishes a leaderboard.

Aider LLM Leaderboards compares language models on code editing benchmarks.

OpenLM Arena compares open language models through leaderboards and benchmark results.

LLMrefs tracks brand visibility, rankings, and citations across generative AI search tools and benchmarks competitors.

SimpleBench evaluates everyday reasoning by comparing language models with human performance.
Popular in AI Data & Analytics
Well-known listings from the same topic.
Dotgetdot.aiForvioforvio.comFluidAI Medicalfluidai.mdApache Zeppelinzeppelin.apache.orgSola Securitysola.securityQuadraticquadratichq.com


SEAL LLM Leaderboard FAQ
What LLM capabilities does the leaderboard benchmark?
It benchmarks agentic coding, frontier reasoning, safety alignment, professional domain performance, multimodal tasks, and more.
Which AI labs' models are included in the rankings?
Rankings include models from OpenAI, Anthropic, Google, Meta, and open-source contributors.
Are benchmark scores accompanied by statistical context?
Yes, all model rankings include performance scores with confidence intervals.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.