

Explore leaderboards with expert-driven LLM benchmarks and updated AI model rankings across coding, reasoning and more.
DeepSWE
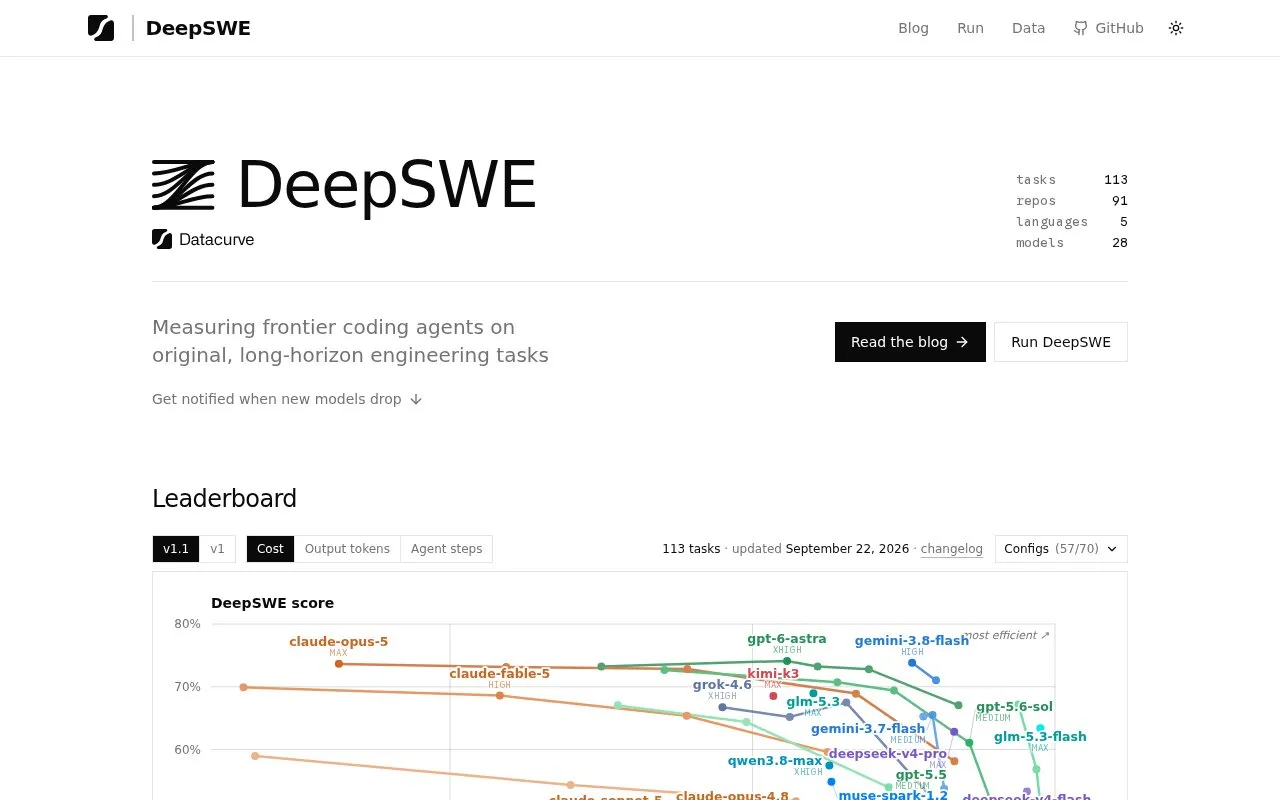
DeepSWE benchmarks coding agents on long-horizon software engineering tasks and publishes a leaderboard.
About DeepSWE
DeepSWE is a benchmark that evaluates frontier coding agents on original, long-horizon software engineering tasks and publishes a public leaderboard. Tasks are written from scratch rather than adapted from existing commits or pull requests, and the task pool spans 91 repositories across 5 languages. The site says prompts are roughly half the length of SWE-bench Pro's, while solutions require more code and output tokens. Verifiers are hand-written to test software behavior rather than implementation details.
Key features
- Leaderboard of 113 original long-horizon software engineering tasks
- Reports Pass@1 with confidence intervals, average cost, output tokens and agent steps
- Contamination-free tasks written from scratch, not adapted from commits or PRs
- Task pool covering 91 repositories across 5 languages
- Hand-written verifiers testing software behavior rather than implementation details
- Version switcher for v1 and v1.1, with filters for models and effort levels
Best for: Teams and researchers who need to compare frontier coding agents on long-horizon software engineering tasks rather than short benchmark problems.
Good for
- Tasks are authored from scratch instead of being adapted from existing commits or pull requests, which the site presents as reducing contamination.
- Verifiers are hand-written to test software behavior rather than implementation details.
- Leaderboard entries pair accuracy with average cost, output token counts and agent steps.
Watch out for
- All models are run on mini-swe-agent for consistency, so results reflect that harness.
- The displayed leaderboard excerpt covers 21 of 28 models and 57 of 70 configurations.
- No pricing information is provided on the site.
DeepSWE at a glance
- Website
- deepswe.datacurve.ai
- Category
- AI & Machine Learning › AI Data & Analytics
- Type
- Website
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
DeepSWE alternatives
Tools and sites you could use instead, ranked by how closely they match.

WebDev Arena ranks AI models on front-end web development tasks and multi-step coding workflows.
ccusage analyzes token usage and estimated costs for coding agent command-line tools.

Code Arena lets users build and test web apps with AI coding models while comparing their accuracy and logic.

SWE-bench publishes benchmark leaderboards for evaluating software engineering agents.

Adala automates data labeling through an autonomous agent framework for organizing labeled datasets.
Open source
24 alternativesPopular in AI Data & Analytics
Well-known listings from the same topic.
Dotgetdot.aiForvioforvio.comFluidAI Medicalfluidai.mdApache Zeppelinzeppelin.apache.orgSola Securitysola.securityQuadraticquadratichq.com


DeepSWE FAQ
What does DeepSWE measure?
It measures frontier coding agents on original, long-horizon software engineering tasks and publishes the results as a leaderboard.
How does DeepSWE address benchmark contamination?
Tasks are written from scratch rather than adapted from existing commits or pull requests; the site states that no model has seen the solution during pretraining.
What does a leaderboard entry include?
Each model entry shows Pass@1 with a confidence interval, average cost, output tokens and agent steps, and entries can be filtered by model, configuration and effort level.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.