
This article discusses challenges in evaluating language models and interpreting benchmark results.
MathArena
MathArena evaluates language models using math benchmarks and publishes model results.
About MathArena
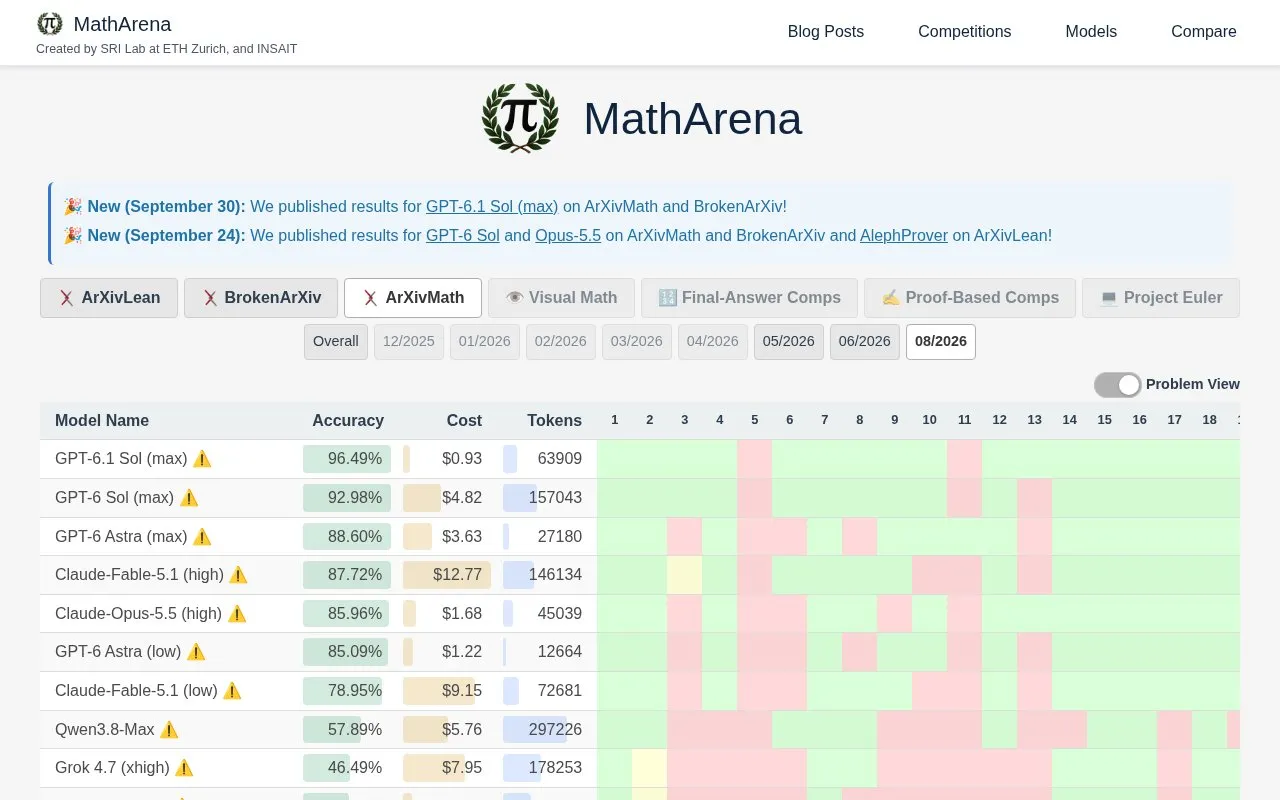
MathArena evaluates language models on math benchmarks and publishes the results on its website. The homepage presents results as leaderboards and tables for named competitions, including AIME, HMMT, USAMO, IMO, and Putnam, along with newer sets called ArXivLean, BrokenArXiv, and ArXivMath. Users can select a competition to load its tables and leaderboard, and click a cell to see the raw model output.
Several sections, including Visual Math, Final-Answer Comps, Proof-Based Comps, and Project Euler, are labeled as deprecated on the homepage. The homepage also lists recent updates, such as new results for specific models and a blog post on generating math content with language models. Pricing is not stated.
Key features
- Leaderboards and result tables for each selected math competition
- Raw model output viewable by clicking a result cell
- Problem view for browsing competition problems
- Results on named contests such as AIME, HMMT, USAMO, IMO, and Putnam
- Monthly result breakdowns for ArXivMath, BrokenArXiv, and ArXivLean
- Blog posts and dated update notes about evaluation results
Best for: Researchers, educators, and AI practitioners who want to compare how language models perform on specific math competitions.
Good for
- Lets users inspect raw model outputs behind reported results
- Covers a range of named competitions, from high school contests to university-level exams
Watch out for
- Several benchmark sections are labeled deprecated on the homepage
- Tables and leaderboards only appear after a competition is selected
MathArena at a glance
- Website
- matharena.ai
- Category
- AI & Machine Learning › AI Data & Analytics
- Type
- Website
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
MathArena alternatives
Tools and sites you could use instead, ranked by how closely they match.

OpenLM Arena compares open language models through leaderboards and benchmark results.

SWE-bench publishes benchmark leaderboards for evaluating software engineering agents.

EQ-Bench publishes benchmarks for emotional intelligence, long-form writing, creative writing, and other model evaluations.

OpenRouter publishes language model rankings based on real usage through its API.

LifeArchitect publishes a reference table of language models and their specifications and data points.
Popular in AI Data & Analytics
Well-known listings from the same topic.
Dotgetdot.aiForvioforvio.comFluidAI Medicalfluidai.mdApache Zeppelinzeppelin.apache.orgSola Securitysola.securityQuadraticquadratichq.com


MathArena FAQ
What can I see after selecting a competition?
The page loads tables and a leaderboard for that competition. Clicking a cell shows the raw model output for that result.
Which competitions are listed on the homepage?
The homepage lists Kangaroo 2025, AIME 2025 and 2026, HMMT competitions, BRUMO 2025, SMT 2025, CMIMC 2025, Apex and Apex Shortlist, USAMO 2025 and 2026, IMO 2025, IMC 2025, Miklós Schweitzer 2025, and Putnam 2025.
Are all benchmark sections current?
No. The homepage labels Visual Math, Final-Answer Comps, Proof-Based Comps, and Project Euler sections as deprecated.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.