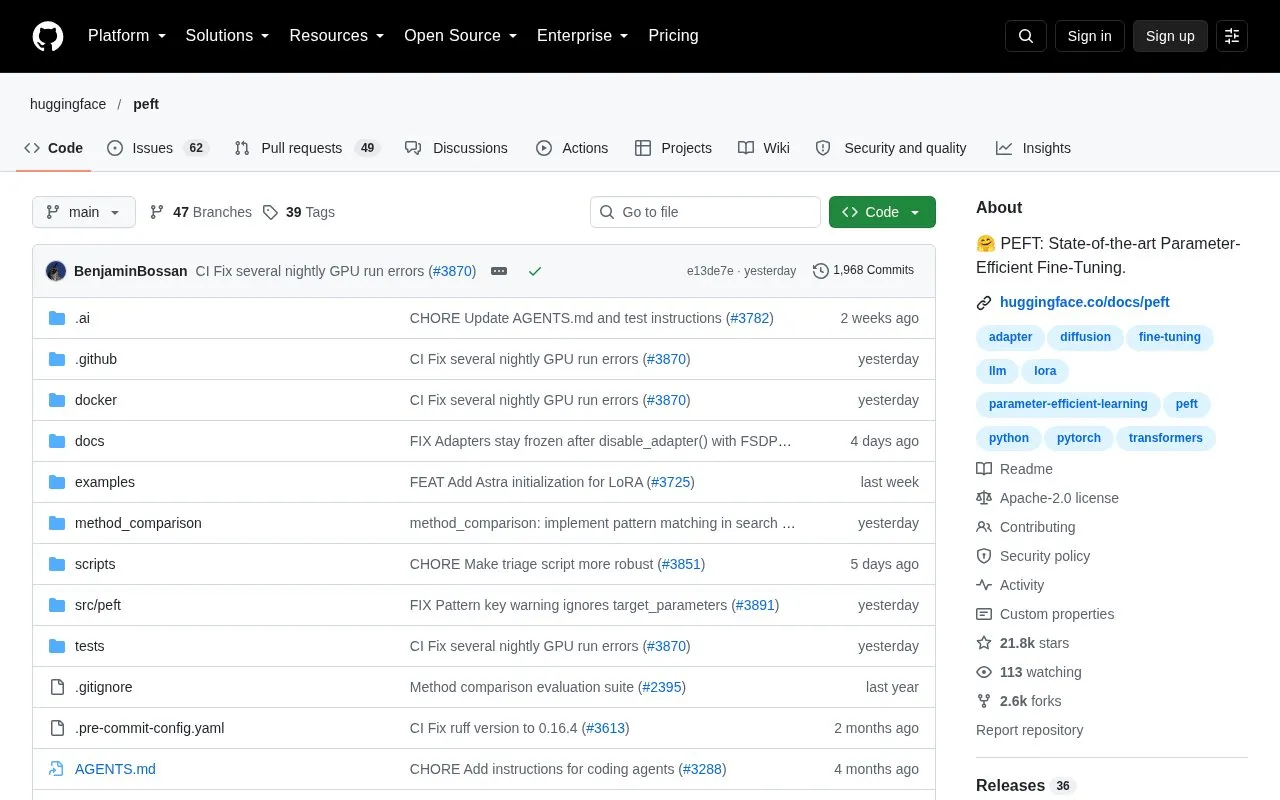
PEFT is an open-source Python library from Hugging Face for parameter-efficient fine-tuning, which adapts large pretrained models to new tasks. Instead of updating all of a model's parameters, PEFT methods train only a small number of added parameters. The project states that this reduces computational and storage costs.
A typical workflow installs the package with pip, wraps a base model and a PEFT configuration such as LoRA using get_peft_model, trains the model, saves it, and later loads it for inference with PeftModel. The project reports memory figures for one setup: an A100 80GB GPU, more than 64GB of CPU RAM, and the ought/raft/twitter_complaints dataset. The source does not say how these results apply to other hardware or tasks. It describes recent PEFT techniques as achieving performance comparable to full fine-tuning, not identical results.
Key features
Trains a small number of added parameters instead of all model parameters
LoRA configuration applied to a base model with get_peft_model
Saving adapter weights with save_pretrained
Loading adapters for inference with PeftModel.from_pretrained
Reporting trainable parameter counts with print_trainable_parameters
Integration with Transformers, Diffusers, and Accelerate
Best for: Machine learning practitioners and researchers who fine-tune large pretrained models and want to reduce compute and storage requirements.
Good for
The project states that PEFT reduces computational and storage costs compared with full fine-tuning.
The memory table lists lower GPU memory for LoRA than for full fine-tuning on the models shown, such as 14.4GB compared with 47.14GB for bigscience/T0_3B.
It is integrated with Transformers, Diffusers, and Accelerate.
Watch out for
The memory figures apply only to the hardware and dataset described in the source.
The source describes PEFT performance as comparable to full fine-tuning, not identical to it.
In the offloading example, LoRA with DeepSpeed CPU offloading uses 52GB of CPU memory for bigscience/mt0-xxl, so lower GPU memory can mean higher CPU memory use.