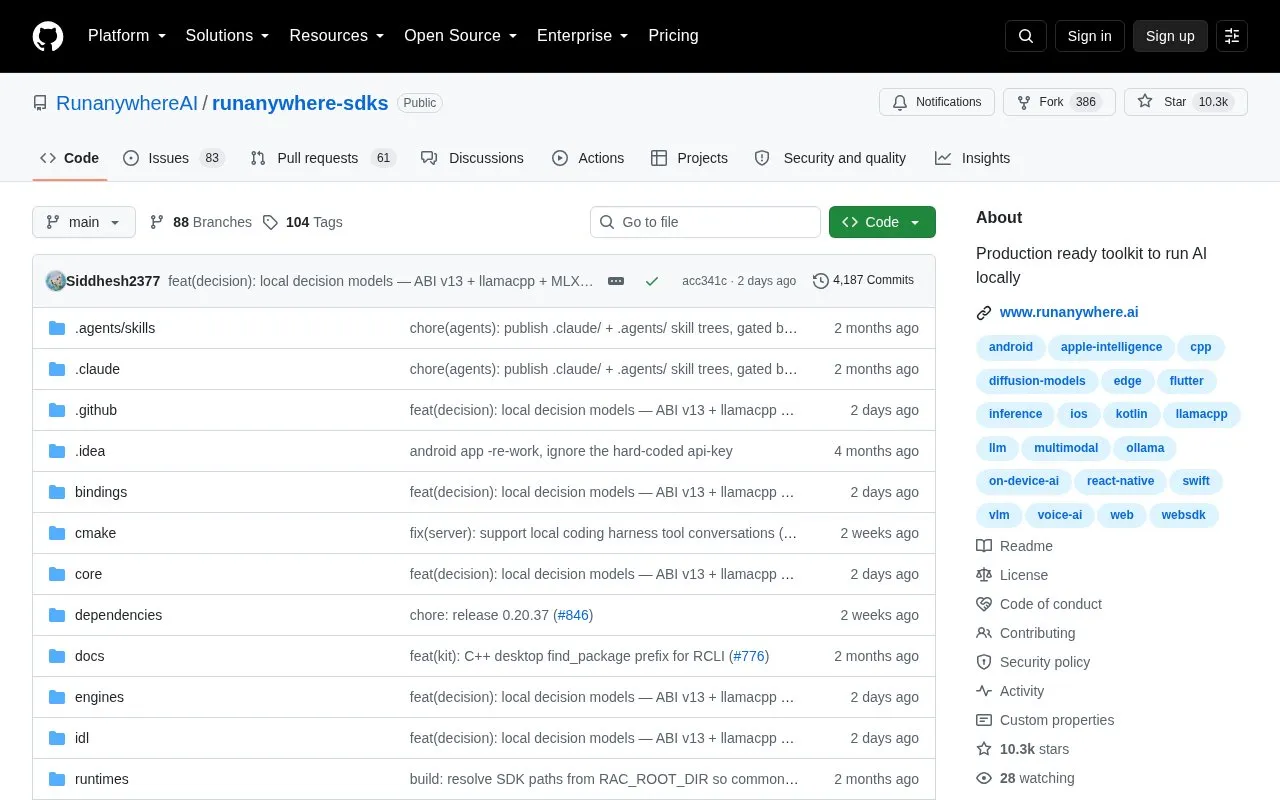
RunAnywhere is a GitHub repository for a toolkit that runs AI models locally on phones, browsers, desktops and servers. It describes eight SDKs built on one C++ core, with a capability registry that routes each call to the engine best suited to the device, plus a Console for managing a fleet. Documented capabilities include LLM chat, structured JSON output, tool calling, vision-language understanding, speech-to-text, text-to-speech, voice agent pipelines, embeddings, local retrieval-augmented generation and image generation.
Key features
On-device LLM chat with token streaming, multi-turn history and LoRA adapters
Speech-to-text via Whisper and Moonshine; TTS via Piper, Kokoro, Kitten and others
Schema-validated JSON output and local tool calling with an agent loop
Vision-language image understanding and local document RAG with streaming
Engine routing across Hexagon NPU, Apple MLX, llama.cpp, ONNX and Core ML
Python package and command-line interface for running models from a terminal
Best for: Developers building mobile, web, desktop or server applications that need AI inference to run on the device rather than in a remote service.
Good for
Described as private by default and offline by design, with models downloaded on first use.
One semantic API is exposed across eight SDKs and multiple hardware-specific engines.
A capability query reports what the current package and device can actually execute.
Watch out for
Wake-word detection is not implemented, and the computer-use action parser is not a full autonomous agent framework.
Some capabilities are platform- or backend-gated, such as image inpainting on the Hexagon NPU, and LiteRT and ExecuTorch are reserved values rather than integrated runtimes.
Enum presence for a capability does not mean the matching engine is installed.
The toolkit is positioned for local, offline execution; the Python quick-start example notes that a model is downloaded on first use.
Does the voice pipeline include wake-word detection?
No. The voice agent pipeline covers VAD, STT, LLM and TTS, but wake-word detection is stated as not implemented.
How can I tell what a given device can run?
Call RunAnywhere.capabilities() (v4) to discover what the current package and device can execute; the presence of an enum value alone does not mean an engine is installed.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim the listing and suggest updates yourself. An editor checks every claim first.