
Google Research introduced Imagen as a text-to-image diffusion model in this research paper.
Stable Diffusion
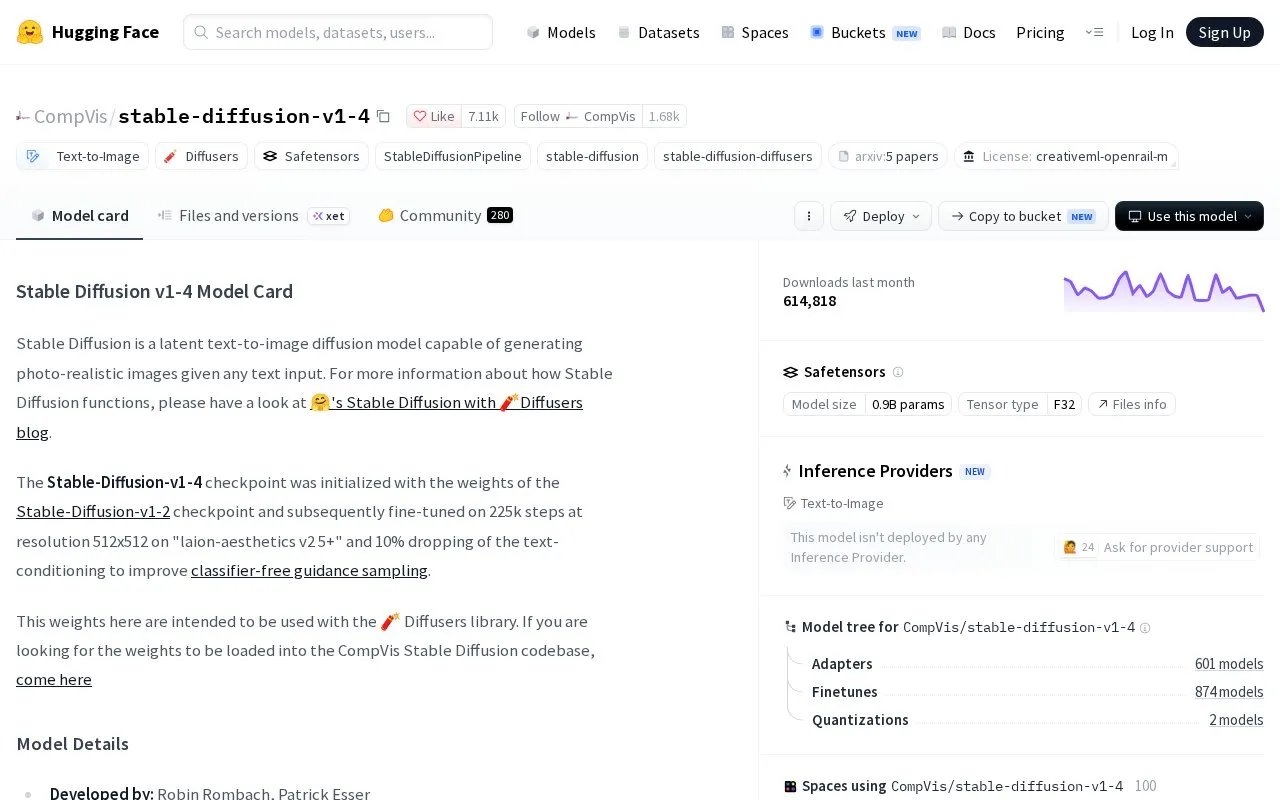
Stable Diffusion v1.4 is a text-to-image model documented with its model card on Hugging Face.
About Stable Diffusion
Stable Diffusion v1.4 is a latent text-to-image diffusion model that generates and modifies images from text prompts. It uses a fixed, pretrained CLIP ViT-L/14 text encoder, and the checkpoint was initialized from the Stable Diffusion v1-2 weights and fine-tuned for 225,000 steps at 512x512 resolution on "laion-aesthetics v2 5+" with 10% dropping of the text-conditioning. The model card is published on Hugging Face by Robin Rombach and Patrick Esser, prompts are in English, and the release is covered by the CreativeML Open RAIL M license. The weights are intended for use with the Diffusers library; a separate location hosts weights for the CompVis Stable Diffusion codebase.
Key features
- Generates and modifies images from English text prompts
- Latent diffusion model with fixed CLIP ViT-L/14 text encoder
- Weights intended for use with the Diffusers library
- PyTorch usage, plus JAX/Flax support for TPUs and GPUs
- Noise scheduler can be swapped, e.g. PNDM or Euler
- float16 loading and attention slicing for GPUs under 4GB RAM
Best for: Developers and researchers who want to run a documented text-to-image diffusion checkpoint through the Diffusers library in Python.
Good for
- Model card documents training, architecture and license details
- Works across PyTorch and JAX/Flax backends, including TPU inference
- CreativeML Open RAIL M license governs use of the weights
Watch out for
- Prompt language is English only
- Weights are intended for Diffusers; CompVis codebase weights are elsewhere
- GPU memory can be a constraint; float16 and attention slicing are suggested below 4GB
Stable Diffusion at a glance
- Category
- AI & Machine Learning › Models & ML Research
- Type
- Online tool
- Pricing
- Not confirmed. Check the site
- Platforms
- Web
- Open source
- Not stated
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
Stable Diffusion alternatives
Tools and sites you could use instead, ranked by how closely they match.
Muse is a text-to-image model that also supports editing images through its generative transformer approach.

The ERNIE blog announces model releases and shares information about training and evaluation results.

TokenVerse presents research on personalizing image generation through multi-concept token modulation.

Image Arena ranks text-to-image generators and lets users compare sample outputs side by side.

Explore BLOOM, a large language model project, through its model page and documentation on Hugging Face.
Popular in Models & ML Research
Well-known listings from the same topic.
Falcon LLMfalconllm.tii.aewTAObittensor.comAlpacacrfm.stanford.edu/2023/03/13/alpaca.htmlSmolVLAhuggingface.co/blog/smolvlaAI Indexhai.stanford.edu/ai-index


Stable Diffusion FAQ
What resolution was this checkpoint fine-tuned at?
It was fine-tuned for 225,000 steps at 512x512 resolution.
What if I have less than 4GB of GPU RAM?
The model card suggests loading the pipeline in float16 precision instead of the default float32 precision and enabling attention slicing.
What language are the prompts in?
The model lists English as its language.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.