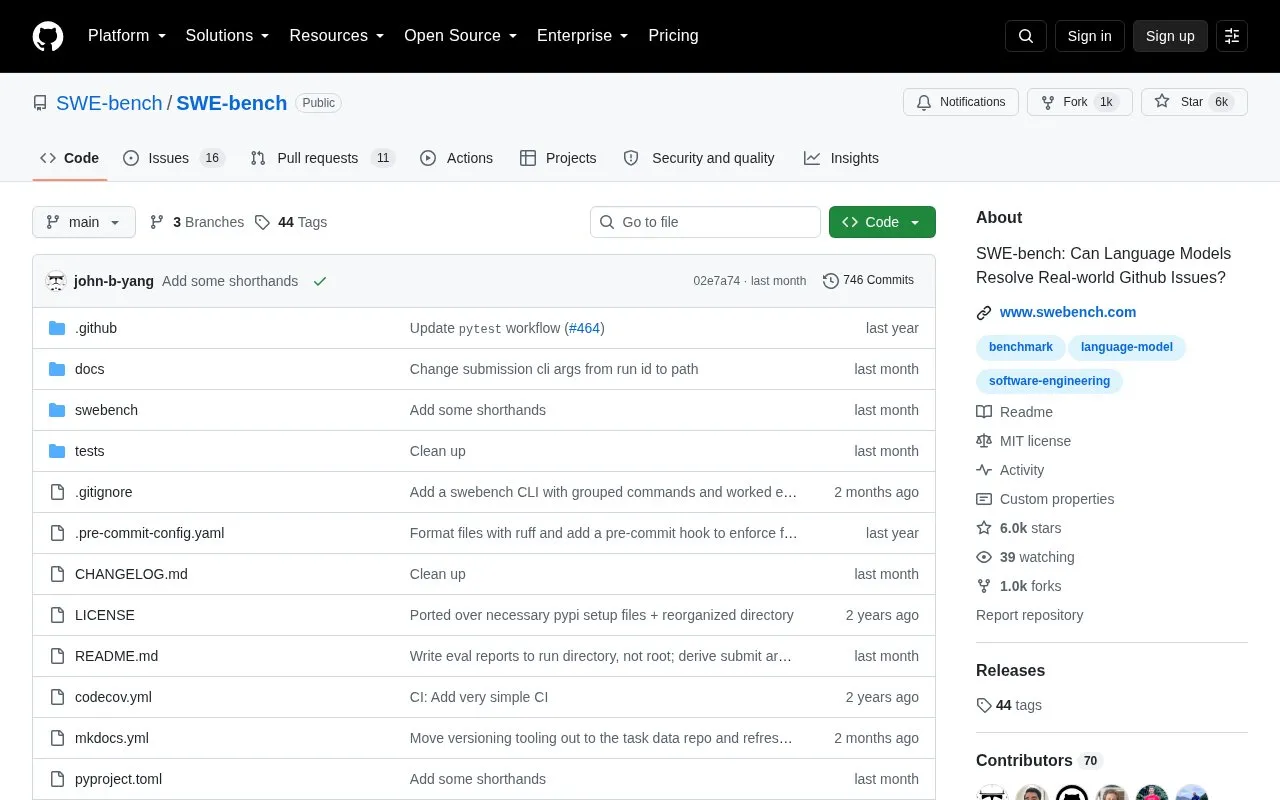
SWE-bench is an open-source benchmark for evaluating large language models on real-world software issues collected from GitHub. Given a codebase and an issue, a model is tasked with generating a patch that resolves the problem.
Datasets are accessed through Hugging Face and evaluated with a Docker-based harness and command-line tools. The v5 CLI builds evaluation images from a task repository, and setup requires installing Docker and installing the package from source.
Key features
Evaluate model-generated patches against real GitHub issues
Load benchmark splits from Hugging Face with Python
Run containerized evaluations using Docker
Evaluate verified, multimodal, multilingual, and full datasets
Generate predictions with mini-SWE-agent via CLI
Publish evaluation runs to a Hugging Face bucket
Best for: Researchers evaluating language models on resolving real GitHub software issues.
Good for
Open source code and data for benchmark tasks
Uses Docker containers for reproducible evaluations
Provides multiple dataset variants including verified and multimodal
Watch out for
Requires Docker installation and setup to run evaluations
v5 CLI requires building images from a task repository
ARM-based systems such as M-series Macs need local builds with --task-repo