
Ollama runs open models for coding agents while keeping model use local.
What Models?
Compare local AI model compatibility with a selected GPU or VRAM, including context size and token speed.
About What Models?
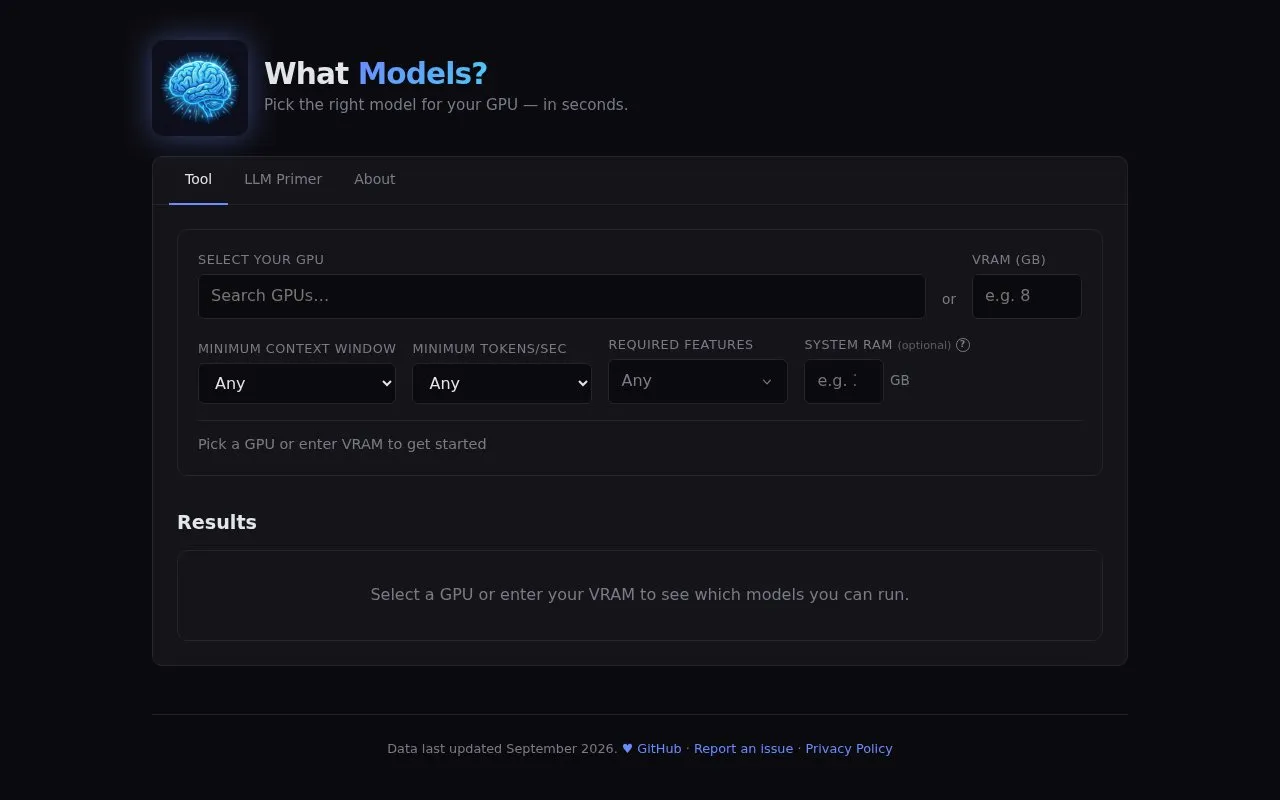
What Models? compares local AI model compatibility with a selected GPU or VRAM amount, including context size and token speed. Users can filter by minimum context window, minimum tokens per second, and required features, and can enter system RAM to account for offloading. Results are shown after a GPU is selected or VRAM is entered.
Key features
- Select a GPU or enter VRAM in GB
- Filter by minimum context window from 2K to 200K
- Filter by minimum speed from 5 to 100 tok/s
- Filter by required features
- Enter system RAM to account for offloading
Best for: People planning to run AI models locally who want to check GPU compatibility.
Good for
- Accepts either a GPU model or a VRAM amount
- Includes context window and token speed filters
- Optional system RAM input covers offloading
What Models? at a glance
- Website
- whatmodelscanirun.com
- Type
- Website
- Pricing
- Not confirmed. Check the site
- Platforms
- Web, Windows
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
What Models? alternatives
Tools and sites you could use instead, ranked by how closely they match.

PrivateGPT provides an API layer for building private AI applications with local model inference.

LM Studio lets users discover, download, and run local language models on Mac, Linux, or Windows.

LocalGPT lets users chat with documents on their local device using GPT models.
Open source
24 alternatives
AnythingLLM is a local-first platform for using AI agents and language models in a self-managed workspace.
Open source
24 alternatives
PrivateGPT provides an API layer for private AI applications using local models, retrieval, tools, and MCP.
Open source
24 alternativesPopular in AI Chatbots & Assistants
Well-known listings from the same topic.
Lumolumo.proton.meMicrosoft Copilotcopilot.microsoft.comLearn Aboutlearning.google.com/experiments/learn-aboutEidoloneidolonai.comFlowHuntflowhunt.ioPine AI19pine.ai


Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.