
CatchTheTornado/text-extract-api
This API extracts and parses text from PDF, Word, and PowerPoint files, with OCR models and options to anonymize documents and remove PII.
About CatchTheTornado/text-extract-api
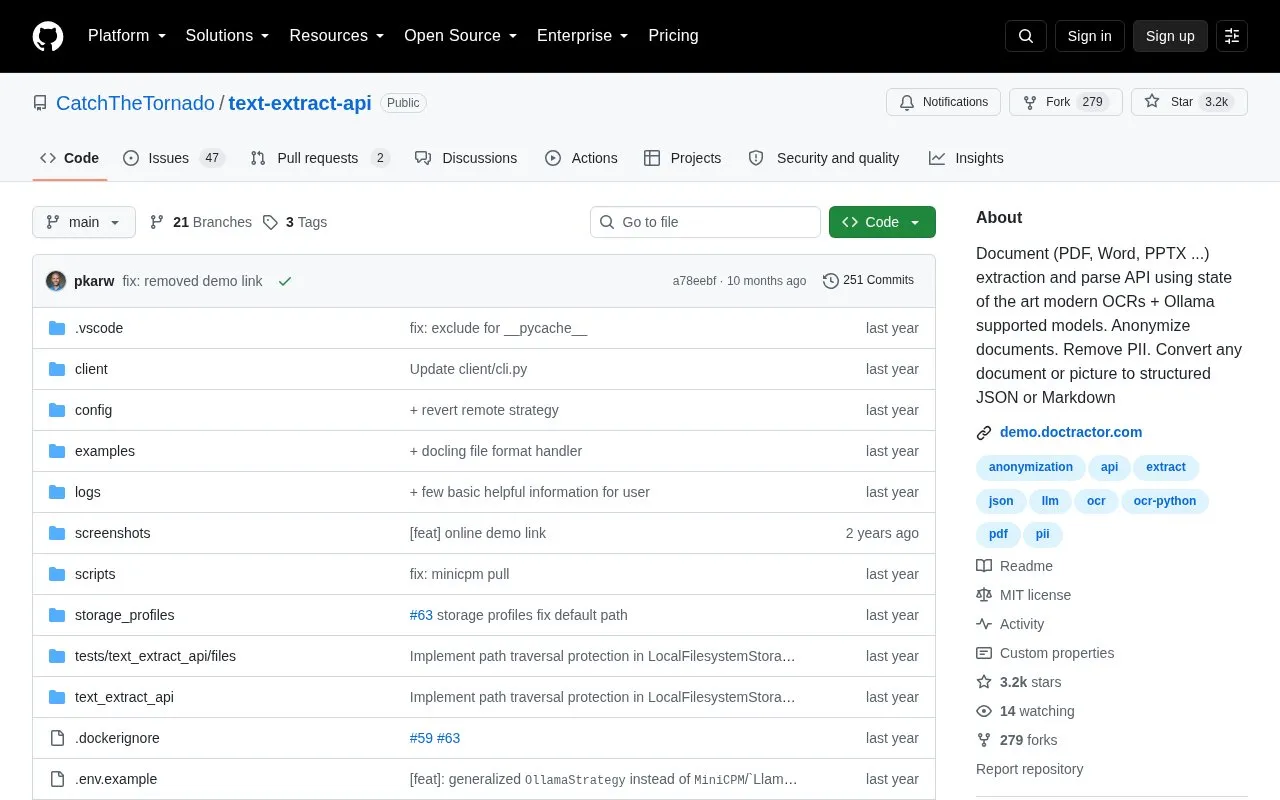
text-extract-api is a document extraction and parse API that works with PDF, Word and PPTX files. It uses state of the art modern OCRs and Ollama supported models, and it can convert a document or picture into structured JSON or Markdown. The project also includes options to anonymize documents and remove PII. The repository is published under the MIT license.
Pricing is not clearly stated.
Key features
- Extracts text from PDF, Word and PPTX files
- Uses modern OCR tools and Ollama supported models
- Converts documents or pictures to structured JSON or Markdown
- Anonymizes documents and removes PII
- Published under the MIT license
CatchTheTornado/text-extract-api at a glance
- Category
- Development › APIs & Databases
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Details verified
- Oct 21, 2026 · Official source
- Open source
- Yes · Source code
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
Guides for APIs & Databases
CatchTheTornado/text-extract-api alternatives
Tools and sites you could use instead, ranked by how closely they match.

For lakehouse architectures, Delta Lake provides an open-source storage framework with support for engines including Spark, Trino, and Hive.
Open source
24 alternatives
Send HTTP requests from the terminal with Posting, an interactive client that can also run over SSH.
Open source
24 alternatives
Vector search and storage are the focus of VectorDB, a Python vector database project.
Open source
24 alternatives
TextRazor provides an NLP API that extracts entities and meaning from text.

Microlink SDK provides a Node.js and browser package for screenshots, PDFs, metadata, scraping, and search through its API.

Build applications on Gel, an open-source database with a data model, graph queries, authentication, and AI features.
Popular in APIs & Databases
Well-known listings from the same topic.
API3api3.orgTwiliotwilio.comDB Browsersqlitebrowser.orgPocketBasepocketbase.ioBrunousebruno.comMeilisearchmeilisearch.com


Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.