

Scrapling provides adaptive web scraping for tasks ranging from single requests to full-scale crawls.
Open source
17 alternativesgrab-site crawls websites for archiving, saves output as WARC, and provides a dashboard and dynamic ignore patterns.
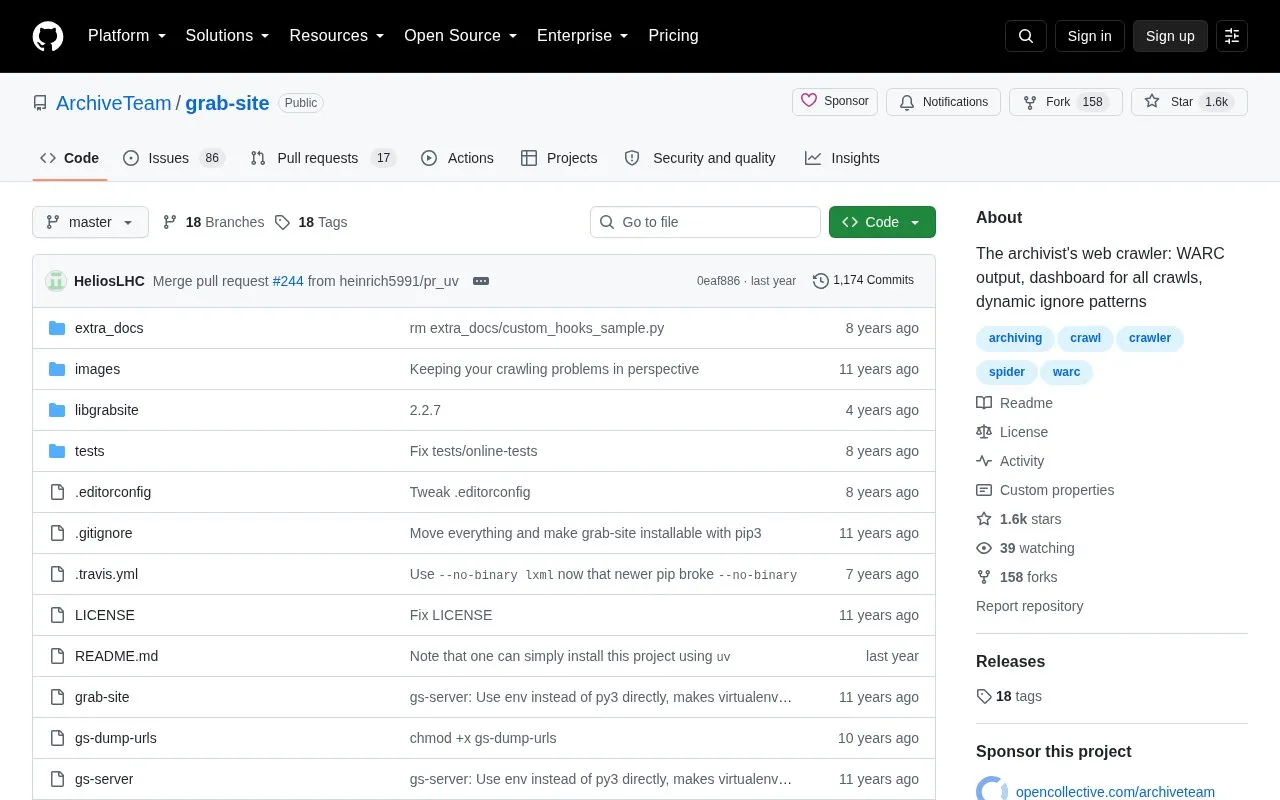
grab-site is a preconfigured crawler for backing up websites. Give it a starting URL and it recursively crawls the site and writes WARC files, using a fork of wpull internally. It runs on specific Python 3.7 or 3.8 versions with set dependencies, with install steps for Ubuntu, Debian, NixOS and macOS, and experimental Windows 10 support.
Pricing is not clearly stated.
Tools and sites you could use instead, ranked by how closely they match.
Scrapling provides adaptive web scraping for tasks ranging from single requests to full-scale crawls.
Crawly extracts structured content from websites by crawling pages across a site.
Awesome Web Scraping collects web scraping libraries, tools, APIs, and manuals across programming languages.
SpiderSuite is a cross-platform web crawler designed for security professionals.
Waymore searches multiple web archives and data sources, including the Wayback Machine, Common Crawl, and URLScan.
Well-known listings from the same topic.
Tell us and an editor will check it.
Claim the listing and suggest updates yourself. An editor checks every claim first.


