

Scrapling provides adaptive web scraping for tasks ranging from single requests to full-scale crawls.
Open source
17 alternativesCrawly extracts structured content from websites by crawling pages across a site.
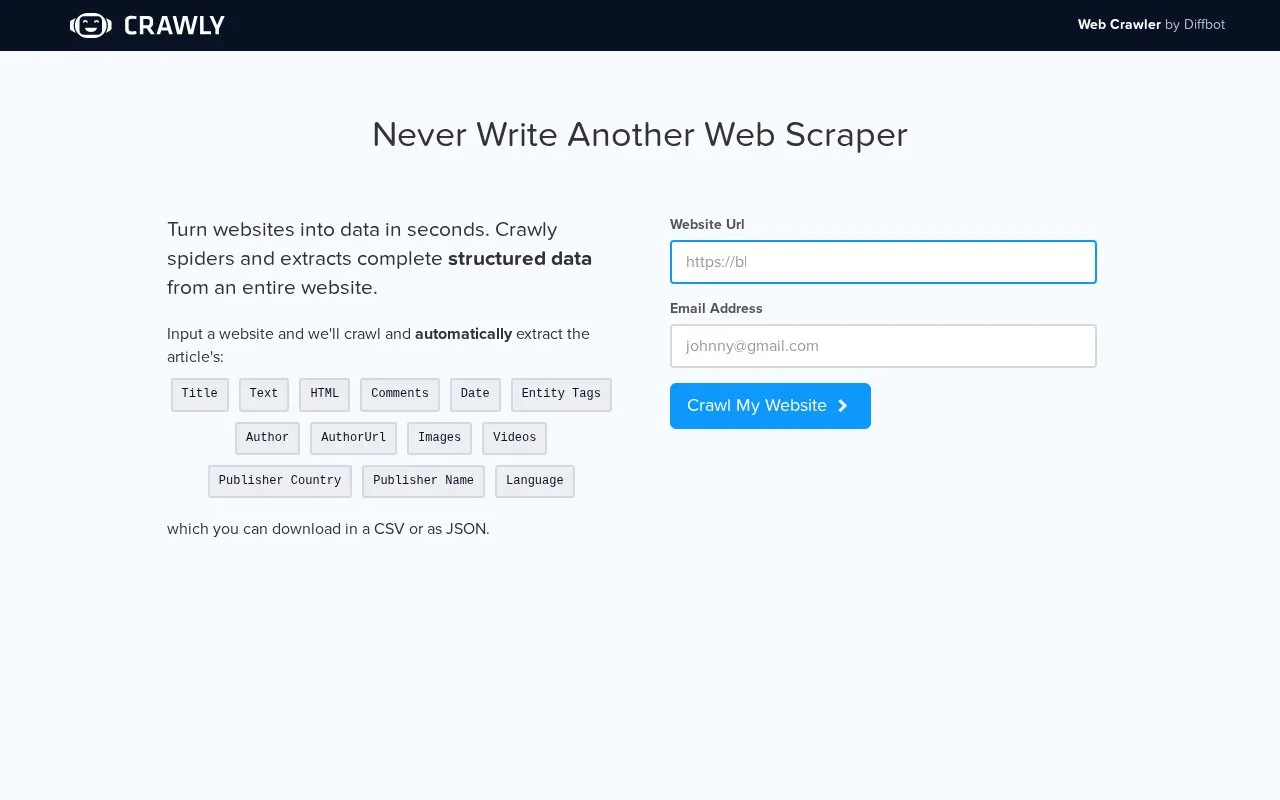
Crawly is a web-based crawler by Diffbot that extracts structured content from websites. A user inputs a website, and the tool crawls pages across the site to extract article fields such as title, text, date, author, images, and publisher information. Results can be downloaded as CSV or JSON.
Tools and sites you could use instead, ranked by how closely they match.
Scrapling provides adaptive web scraping for tasks ranging from single requests to full-scale crawls.
Awesome Web Scraping collects web scraping libraries, tools, APIs, and manuals across programming languages.
This Cloudflare Workers-based web scraper extracts text from selected page elements or reads an attribute.
80legs offers customizable web scraping and cloud-based crawling tools for running web crawls.
grab-site crawls websites for archiving, saves output as WARC, and provides a dashboard and dynamic ignore patterns.
Crawl4AI turns website content into Markdown for language models and AI agents through an open-source crawling framework.
Well-known listings from the same topic.
Tell us and an editor will check it.
Claim the listing and suggest updates yourself. An editor checks every claim first.


