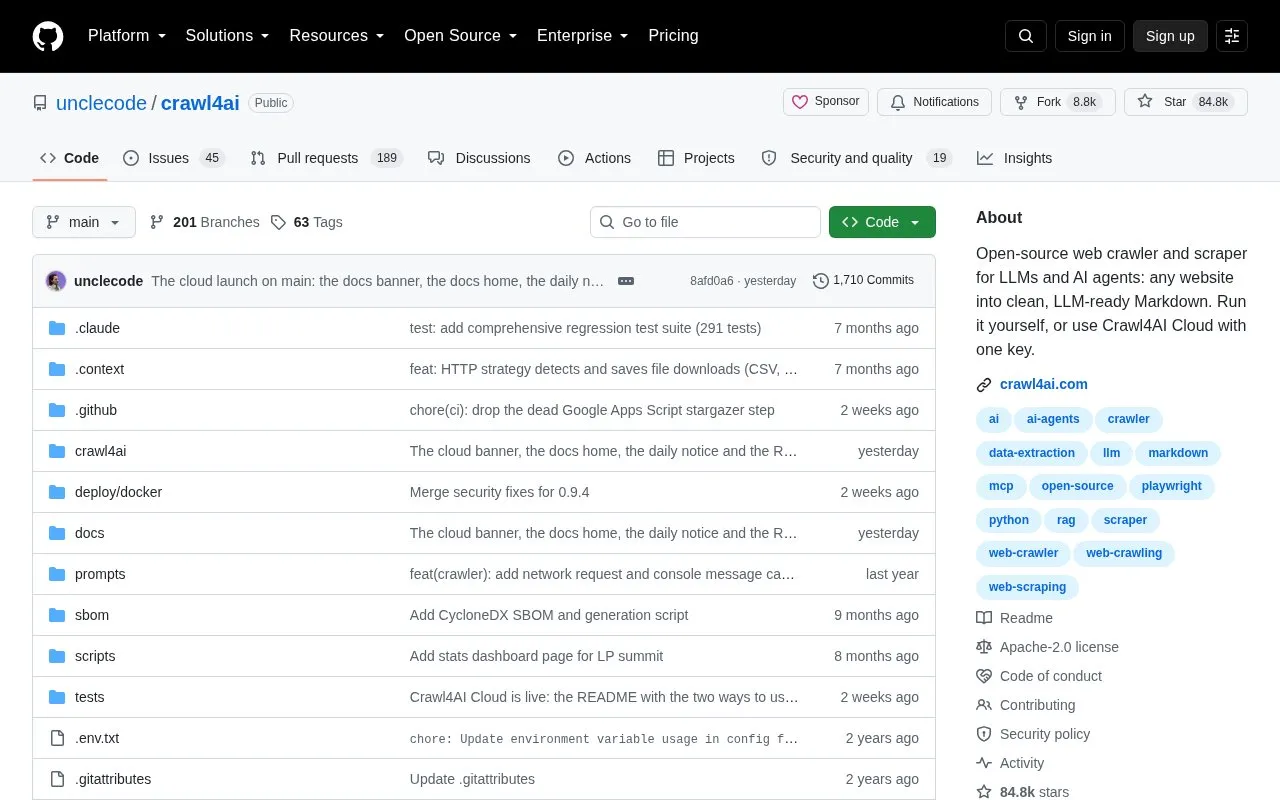
Crawl4AI converts website content into Markdown for use with language models, RAG workflows, data pipelines and AI agents. It can be run as a Python library, Docker server or CLI, and is also available as a hosted cloud API that provides scrape, search, answer and extract functions and connects to agents through MCP.
When self-hosted, users manage browsers, proxies and hosting. The comparison in the source lists web search only for the cloud option.
Key features
Converts website content into Markdown for language models
Removes menus, footers and boilerplate with filtered Markdown
Supports sessions, proxies, cookies, user scripts and hooks
Offers scrape, search, answer and extract through one API key
Processes multiple URLs at once with batch and jobs endpoints
Works as Python library, Docker server, CLI or hosted service
Best for: Developers building RAG pipelines, data extraction workflows, or AI agents that need web content as Markdown.
Good for
Open-source code that can be run locally or in Docker without a key
Provides Markdown output with headings, tables, code and citation hints
Offers self-hosted and hosted options with agent connection through MCP
Watch out for
Self-hosted use requires managing browsers, proxies and hosting
Library and self-hosted server versions do not include web search