

Qwen3-Coder provides a code-focused model in the Qwen family of large language models.
Qwen3-VL
The Qwen3-VL model family provides multimodal large language models from Alibaba Cloud.
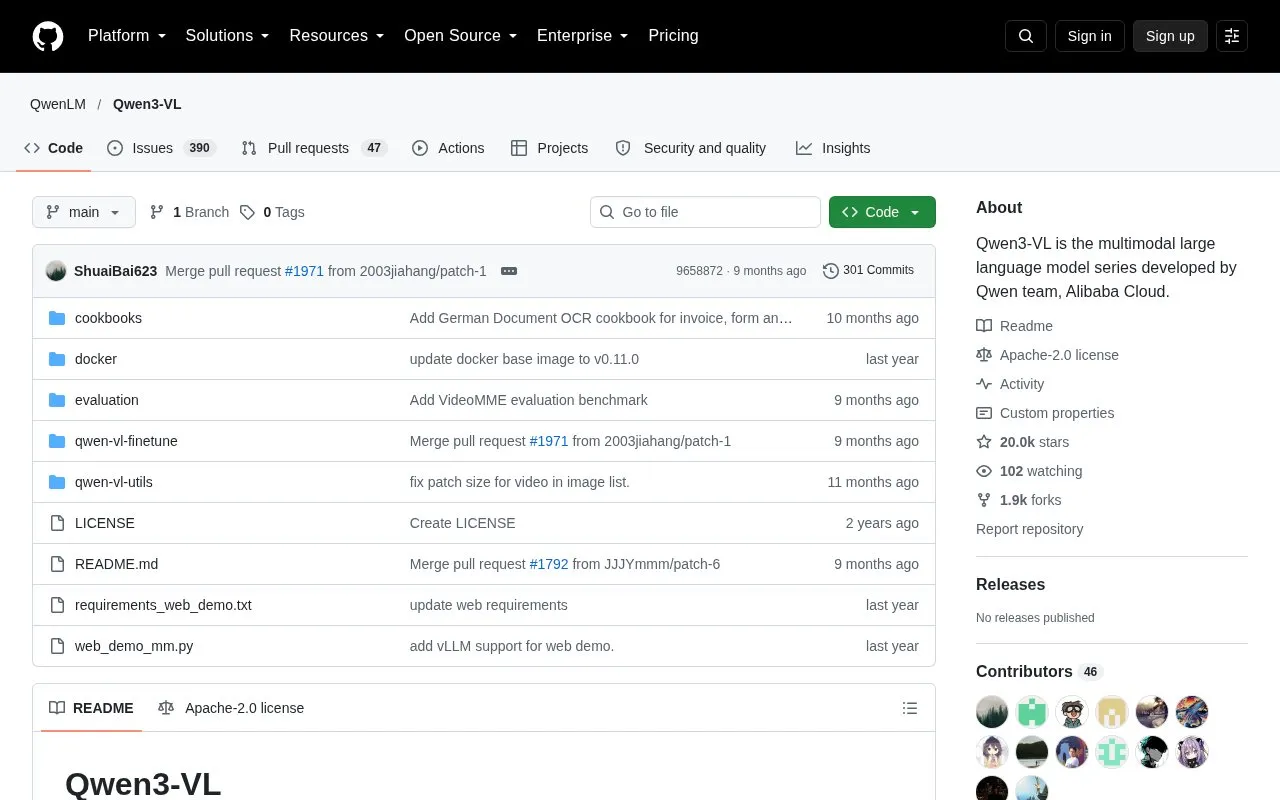
About Qwen3-VL
Qwen3-VL is a GitHub repository for the Qwen3-VL series of multimodal large language models, developed by the Qwen team at Alibaba Cloud. The models are described as vision-language models that process images and video along with text. The series is offered in Dense and MoE architectures and in Instruct and reasoning-enhanced Thinking editions. The repository includes cookbooks, Docker files, evaluation code, fine-tuning code, a web demo, and utilities. The README lists capabilities such as GUI operation, code generation from images, spatial perception, long-context video understanding, and OCR.
The README's news section lists releases from 2024 through 2025, including several Qwen3-VL sizes and FP8 versions, along with a technical paper. Pricing is unknown from the source. The excerpt does not state hardware requirements, the specific license terms, or how each capability performs by model size or edition.
Key features
- Native 256K context window, expandable to 1M tokens
- Visual agent that operates PC and mobile graphical user interfaces
- Generates Draw.io, HTML, CSS, and JavaScript from images or videos
- 2D grounding and 3D grounding for spatial reasoning
- OCR for 32 languages, including low-light, blurred, or tilted text
- Dense and MoE architectures with Instruct and Thinking editions
Best for: Developers and researchers who want open source vision-language models and code for building, evaluating, or fine-tuning multimodal systems.
Good for
- Open source repository with a LICENSE file and code for cookbooks, evaluation, and Docker
- Includes fine-tuning code, which the news section says was released for earlier Qwen2-VL and Qwen2.5-VL models
- Available in several model sizes and in both Instruct and Thinking editions
Qwen3-VL at a glance
- Website
- github.com/QwenLM/Qwen3-VL
- Category
- AI & Machine Learning › Models & ML Research
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Open source
- Yes · Source code
- Language
- English
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
Qwen3-VL alternatives
Tools and sites you could use instead, ranked by how closely they match.

The Qwen3 model series was developed by the Qwen team at Alibaba Cloud.

Janus combines multimodal understanding and image generation models in a unified model series.
Open source
24 alternatives
Point·E is a research project that generates 3D point clouds using diffusion models.
Open source
24 alternatives
Qwen3-Omni understands text, audio, images, and video, and can generate speech in real time.
Open source
24 alternatives
MobiLlama is a small language model designed for edge devices, according to its repository description.
Open source
24 alternativesPopular in Models & ML Research
Well-known listings from the same topic.
Falcon LLMfalconllm.tii.aeERNIEernie.baidu.comTokenVersetoken-verse.github.iowTAObittensor.comAlpacacrfm.stanford.edu/2023/03/13/alpaca.htmlSmolVLAhuggingface.co/blog/smolvla


Qwen3-VL FAQ
What context length does Qwen3-VL support?
The README describes a native 256K context, expandable to 1M.
Does the repository include fine-tuning code?
The news section says code for fine-tuning Qwen2-VL and Qwen2.5-VL was released on 2025.04.08. The repository also contains a qwen-vl-finetune folder.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.