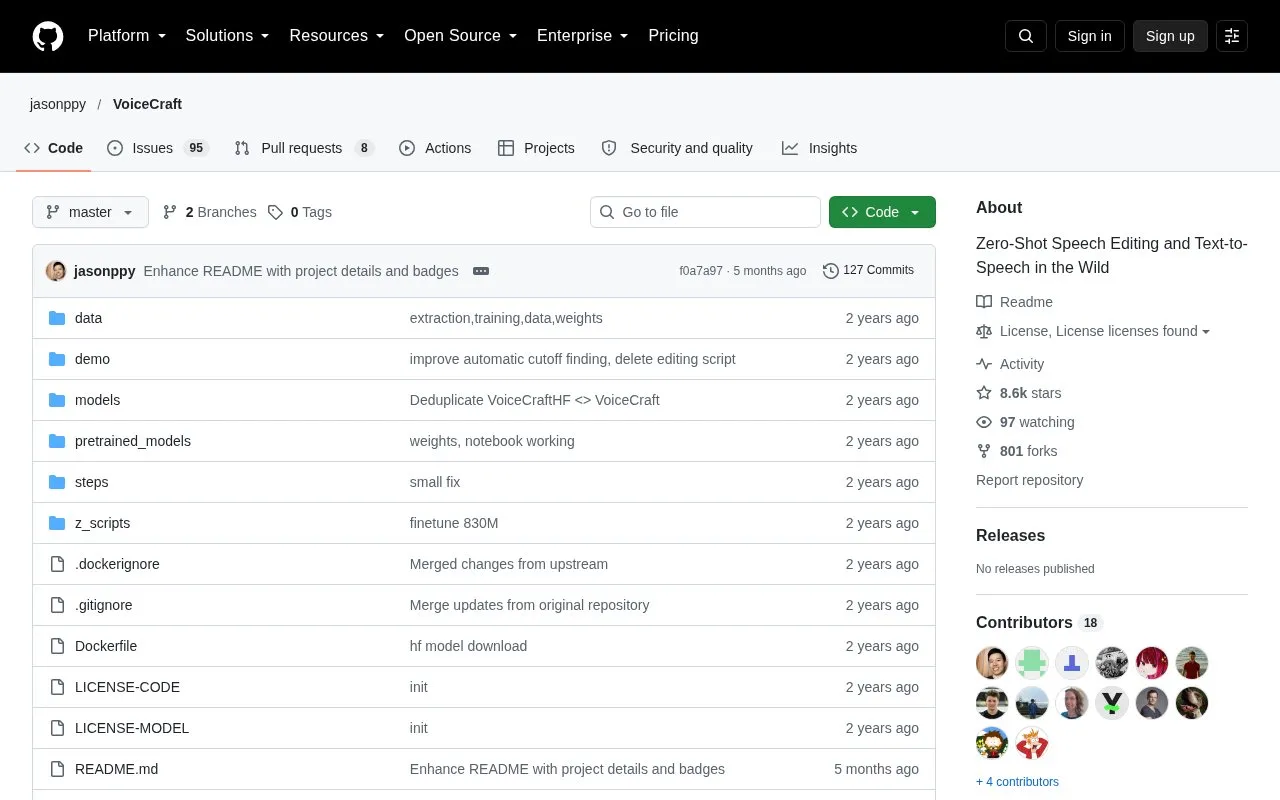
VoiceCraft is a GitHub repository for zero-shot speech editing and text-to-speech (TTS) generation. According to the project README, it is a token infilling neural codec language model. The README states that it performs well on speech editing and zero-shot TTS using in-the-wild data such as audiobooks, internet videos, and podcasts. To clone or edit a voice it has not been trained on, it needs only a few seconds of reference audio.
The project can be run in several ways: in Google Colab, with Docker, from a local installation, or as a standalone command-line script. The Gradio interface is also available on Hugging Face Spaces. Model weights are published on Hugging Face. The README notes a length limit for one fine-tuned TTS model: the combined prompt and generation length must be 16 seconds or less. Training and fine-tuning are described in the README, but the project lists better guidance on these as a to-do item.
Key features
Speech editing through token infilling with a neural codec language model
Zero-shot text-to-speech from a few seconds of reference audio
Pretrained TTS models in 330M and 830M parameter sizes
Gradio web interface runnable locally, in Colab, or on Hugging Face Spaces
Command-line scripts for TTS and speech editing with adjustable inputs and settings
Docker setup tested on Linux and Windows
Best for: Researchers and developers who want to experiment with speech editing or text-to-speech models and are comfortable setting up Python environments or using Colab.
Good for
Several run options, including Google Colab, Docker, local installation, and standalone scripts
Requires only a few seconds of reference audio to clone or edit an unseen voice
The README describes state-of-the-art results on in-the-wild audio, including audiobooks, internet videos, and podcasts
Watch out for
For the fine-tuned giga330M TTS model, the combined prompt and generation length must not exceed 16 seconds
Docker setup on Linux requires the NVIDIA container toolkit
The README lists better guidance on training and fine-tuning as a to-do item