
AWS Data Wrangler
AWS Data Wrangler connects Pandas with AWS data services and databases, including Athena, Glue, Redshift, and S3.
About AWS Data Wrangler
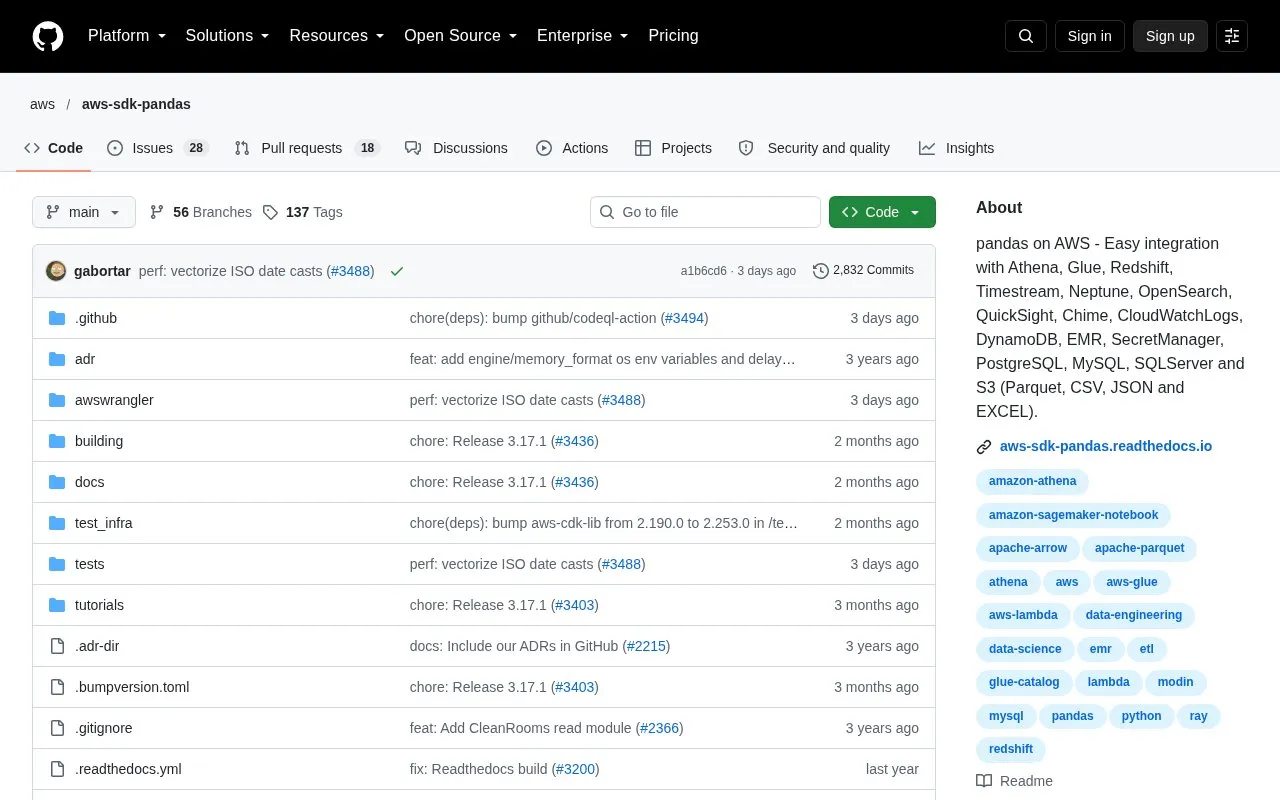
AWS Data Wrangler is an open source Python library, published on GitHub under the name AWS SDK for pandas (awswrangler), that connects pandas DataFrames with AWS data services and databases. The project is an AWS Professional Service open source initiative. The repository's quick start shows examples that write a DataFrame to Amazon S3 as Parquet with an optional Glue Catalog table, read S3 data back, run Amazon Athena SQL queries, connect to Redshift through a Glue connection, and write and query Amazon Timestream.
The library can be installed with pip or conda. From version 3.0, optional modules such as Redshift support must be installed explicitly, for example with pip install 'awswrangler[redshift]'. The project also states that workflows can run at scale by using Modin and Ray to distribute processing across a cluster of workers.
Key features
- Writes pandas DataFrames to Amazon S3 as Parquet, with optional Glue Catalog table registration.
- Reads S3 data into DataFrames, including Parquet datasets.
- Runs Amazon Athena SQL queries and returns the results as DataFrames.
- Connects to Redshift through a Glue connection and reads data, including Redshift Spectrum tables.
- Writes data to and queries data from Amazon Timestream.
- Distributes workflows across a cluster of workers using Modin and Ray.
Best for: Python developers and data practitioners who already use pandas and need to move data between pandas and AWS data services.
Good for
- Open source, with the source code and license available in the repository.
- Can be installed with pip or conda.
Watch out for
- From version 3.0, optional modules such as Redshift support must be installed explicitly.
AWS Data Wrangler at a glance
- Category
- Development › Developer Tools
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Open source
- Yes · Source code
- Language
- English
- Last checked
- Oct 6, 2026 · Online when checked
- Listed
- Oct 5, 2026
Guides for Developer Tools
AWS Data Wrangler alternatives
Tools and sites you could use instead, ranked by how closely they match.

DataComPy compares Pandas, Polars, Spark, and Snowpark dataframes, with output that includes comparison statistics.
Open source
24 alternatives
Koalas implements the pandas DataFrame API on Apache Spark and is deprecated; for Apache Spark 3.2 and above, use PySpark directly.
Open source
24 alternatives
Python developers can use Dash to build data apps and dashboards without requiring JavaScript.
Open source
24 alternatives
Machine learning pipelines can use whylogs, an open-source library for logging data quality and model performance.
Open source
24 alternatives
For Python data preparation, DataPrep offers an open-source low-code library to collect, clean, and visualize data.
Open source
24 alternatives
The Geni project provides a Clojure dataframe library that runs on Apache Spark.
Open source
24 alternativesPopular in Developer Tools
Well-known listings from the same topic.
AppDevToolsappdevtools.comCommand Not Foundcommand-not-found.comTestFlighttestflight.apple.com/join/A8GwCnq8Sourcegraphabout.sourcegraph.comProject Wallaceprojectwallace.comCarbon Calculatorwebsitecarbon.com


AWS Data Wrangler FAQ
How do I install AWS SDK for pandas (awswrangler)?
Use pip install awswrangler or conda install -c conda-forge awswrangler. For Redshift support from version 3.0 onward, use pip install 'awswrangler[redshift]'.
Which databases does the library connect to?
The repository lists PostgreSQL, MySQL, and SQLServer, and a tutorial covers Redshift, MySQL, PostgreSQL, SQL Server, and Oracle.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.