

Vocova transcribes audio and video into text in more than 100 languages and accepts imports from named services.
ggerganov/whisper.cpp
The whisper.cpp repository provides a C and C++ port of OpenAI’s Whisper model.
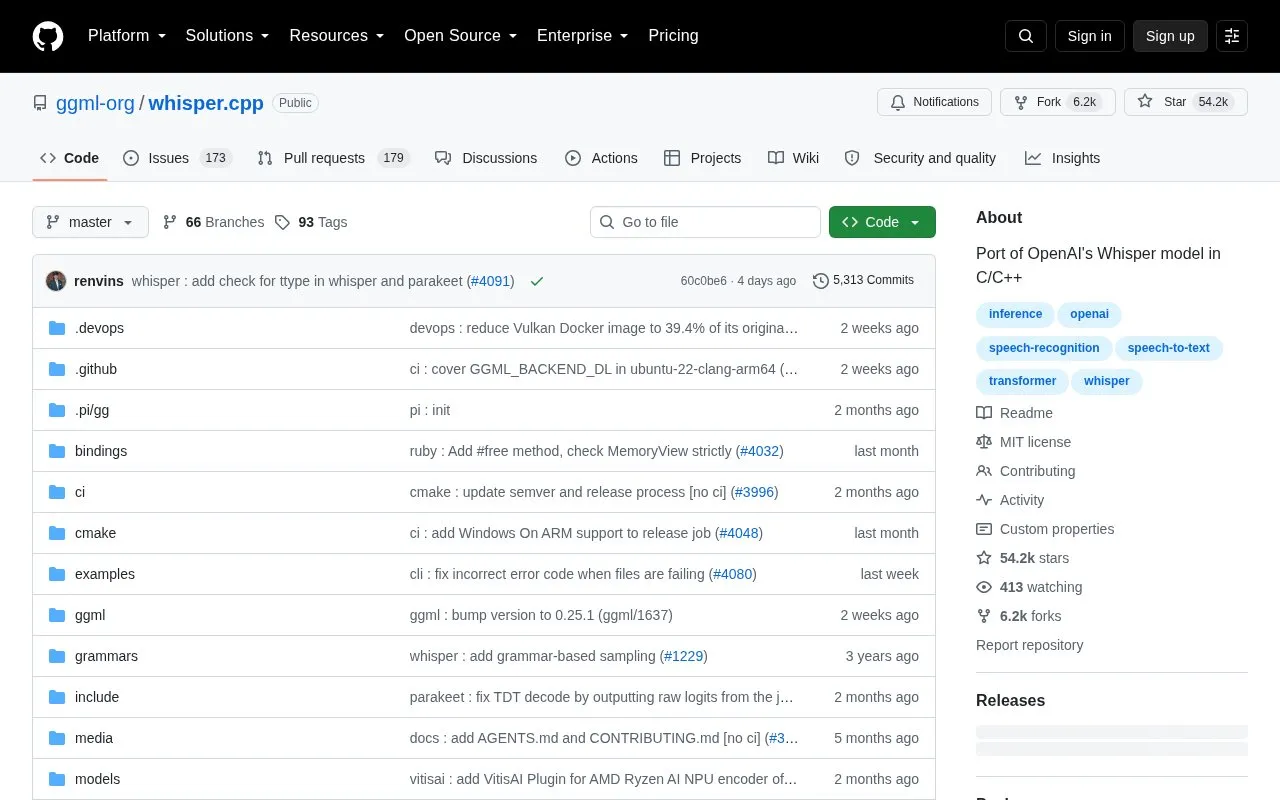
About ggerganov/whisper.cpp
whisper.cpp is an open source C and C++ port of OpenAI's Whisper automatic speech recognition model. It implements inference in plain C/C++ without dependencies, with core logic in whisper.h and whisper.cpp and supporting code from the ggml library. It provides a C-style API, mixed F16/F32 precision, integer quantization, and Voice Activity Detection (VAD).
It supports CPU-only inference and options for NVIDIA GPU, AMD ROCm, Vulkan, OpenVINO, and several NPUs, and is described as running fully offline on-device. Listed platforms include Mac OS, iOS, Android, Linux/FreeBSD, Windows, WebAssembly, Raspberry Pi, Java, and Docker. Use requires a Whisper model converted to ggml format, and the whisper-cli example accepts only 16-bit WAV files, so other audio must be converted first.
Key features
- C/C++ port of Whisper for speech-to-text inference without dependencies
- CPU-only inference with support for NVIDIA, AMD, Vulkan and other accelerators
- Integer quantization of ggml models to use less memory and disk space
- C-style API with core implementation in whisper.h and whisper.cpp
- Includes Voice Activity Detection (VAD)
- Offline on-device transcription on platforms including iOS, Android and Raspberry Pi
Best for: Developers who need to integrate offline Whisper transcription into apps on desktop, mobile, and embedded systems.
Good for
- Open source implementation in plain C/C++ without dependencies
- Runs fully offline on-device, demonstrated on iPhone 13 and Apple Silicon via Metal
- Supports multiple operating systems and CPU, GPU, and NPU options
Watch out for
- whisper-cli example works only with 16-bit WAV files, so other audio needs conversion
- Requires Whisper models converted to ggml format before use
- Larger models need substantial disk and memory, with large listed at 2.9 GiB disk and ~3.9 GB memory
ggerganov/whisper.cpp at a glance
- Category
- AI & Machine Learning › AI Speech Transcription
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Open source
- Yes · Source code
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
ggerganov/whisper.cpp alternatives
Tools and sites you could use instead, ranked by how closely they match.

WhisperS2T is an optimized speech-to-text pipeline for the Whisper model with support for multiple inference engines.
Open source
24 alternatives
OpenQuack provides local voice dictation on macOS, inserting Whisper transcripts at the cursor.
Open source
24 alternatives
WhisperAPI transcribes audio and video through an API powered by OpenAI Whisper, with support for more than 98 languages.

WhisperTranscribe transcribes audio with Whisper AI and includes speaker recognition and automatic meeting recording.

AI Dictation turns mixed Russian, Ukrainian, or Belarusian speech into text while preserving English work terms.
Free trial
24 alternativesPopular in AI Speech Transcription
Well-known listings from the same topic.
Transgatetransgate.aiWavewave.coRev.airev.aiGood Tapegoodtape.ioTalkNotestalknotes.ioSpeech to Notespeechtonote.com


ggerganov/whisper.cpp FAQ
What audio format does the whisper-cli example accept?
It currently runs only with 16-bit WAV files. Convert other input first, for example with: ffmpeg -i input.mp3 -ar 16000 -ac 1 -c:a pcm_s16le output.wav
How do I run a basic transcription?
Clone the repository, download a ggml-format model such as base.en with sh ./models/download-ggml-model.sh base.en, build with cmake, then run ./build/bin/whisper-cli -f samples/jfk.wav
How much disk and memory do the models use?
Listed usage is tiny: 75 MiB disk, ~273 MB memory; base: 142 MiB disk, ~388 MB memory; small: 466 MiB disk, ~852 MB memory; medium: 1.5 GiB disk, ~2.1 GB memory; large: 2.9 GiB disk, ~3.9 GB memory.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.