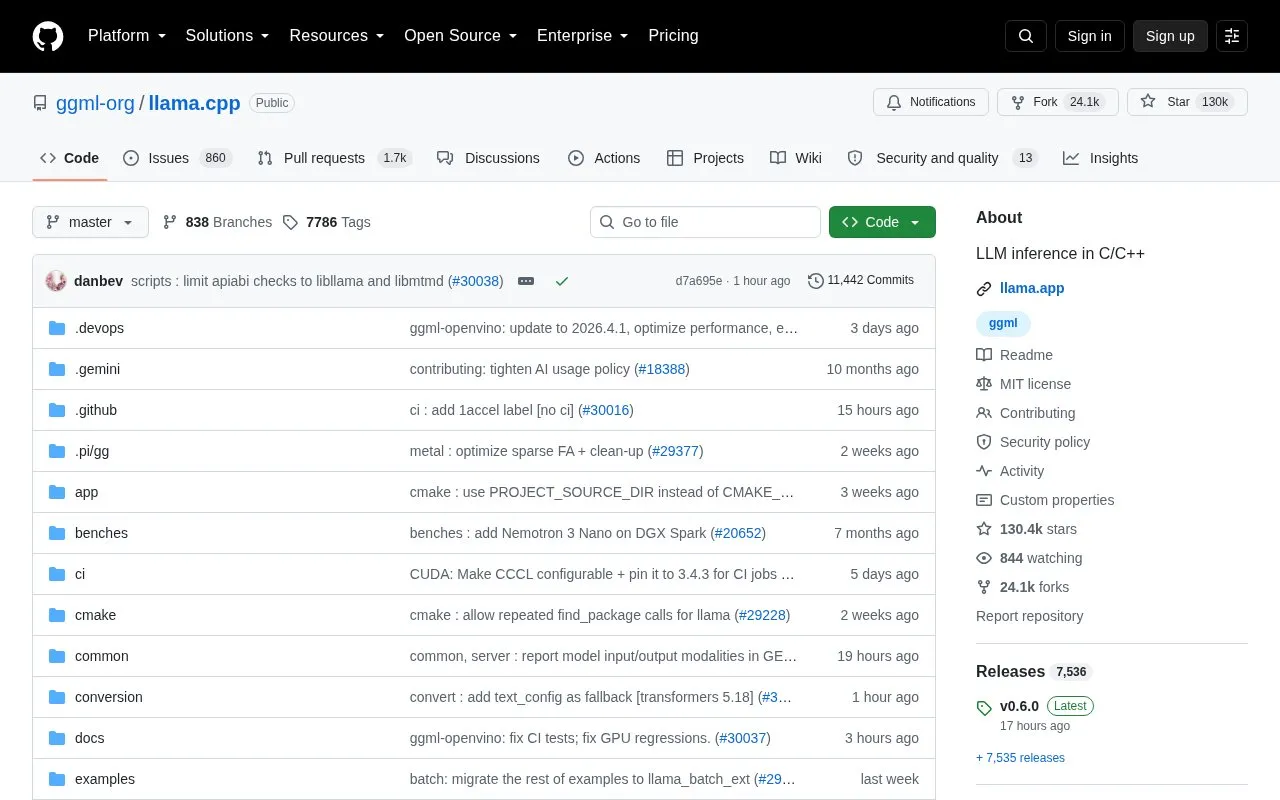
llama.cpp is an open-source C/C++ project for running large language model (and vision-language model) inference with minimal setup, both locally and in the cloud. It is built on the ggml library and aims to work across a wide range of hardware, including Apple silicon, x86 CPUs, RISC-V, and a long list of GPU and accelerator backends.
The project ships command-line tools, a completion tool, an OpenAI-compatible server and a built-in web UI, and models can be downloaded and run directly from Hugging Face. Quantization from 1.5-bit to 8-bit reduces memory use, and CPU+GPU hybrid inference can partially accelerate models larger than total VRAM. It is a developer-oriented repository rather than a hosted consumer chat service, and the source provides no pricing information.
Key features
LLM and VLM inference implemented in plain C/C++ without dependencies
Optimized for Apple silicon via ARM NEON, Accelerate and Metal
AVX, AVX2, AVX512 and AMX support for x86 architectures
GPU backends include CUDA, HIP, MUSA, Vulkan, SYCL and WebGPU
Integer quantization from 1.5-bit to 8-bit reduces memory use
CPU+GPU hybrid inference for models larger than available VRAM
Best for: Developers and researchers who want to run LLM or VLM inference themselves across a range of hardware, with control over quantization, backends and serving.
Good for
Plain C/C++ implementation without external dependencies
Broad hardware coverage across CPU, GPU, NPU and accelerator backends
Can download and run GGUF models directly from Hugging Face via the CLI or server
Watch out for
No pricing information is given on the repository page
Getting started involves installing a script, using Docker, downloading binaries, or building from source
Aimed at developers using CLI and server tools rather than packaged end-user chat software
Options listed include a curl or PowerShell install script, Docker, pre-built binaries from the releases page, or building from source by cloning the repository.
Can llama.cpp serve an OpenAI-compatible API?
Yes. Running `llama serve` with a model launches an OpenAI-compatible API server, and a built-in web UI can be used against it.
Which hardware backends are supported?
The documented list includes CUDA, HIP, MUSA, Metal, Vulkan, SYCL, WebGPU, OpenCL, CANN, Hexagon, IBM zDNN, RPC, ZenDNN, BLAS, BLIS, VirtGPU, and OpenVINO (in progress), among others.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim the listing and suggest updates yourself. An editor checks every claim first.