
brozzler
Brozzler crawls the web through a distributed browser-based crawler project from the Internet Archive.
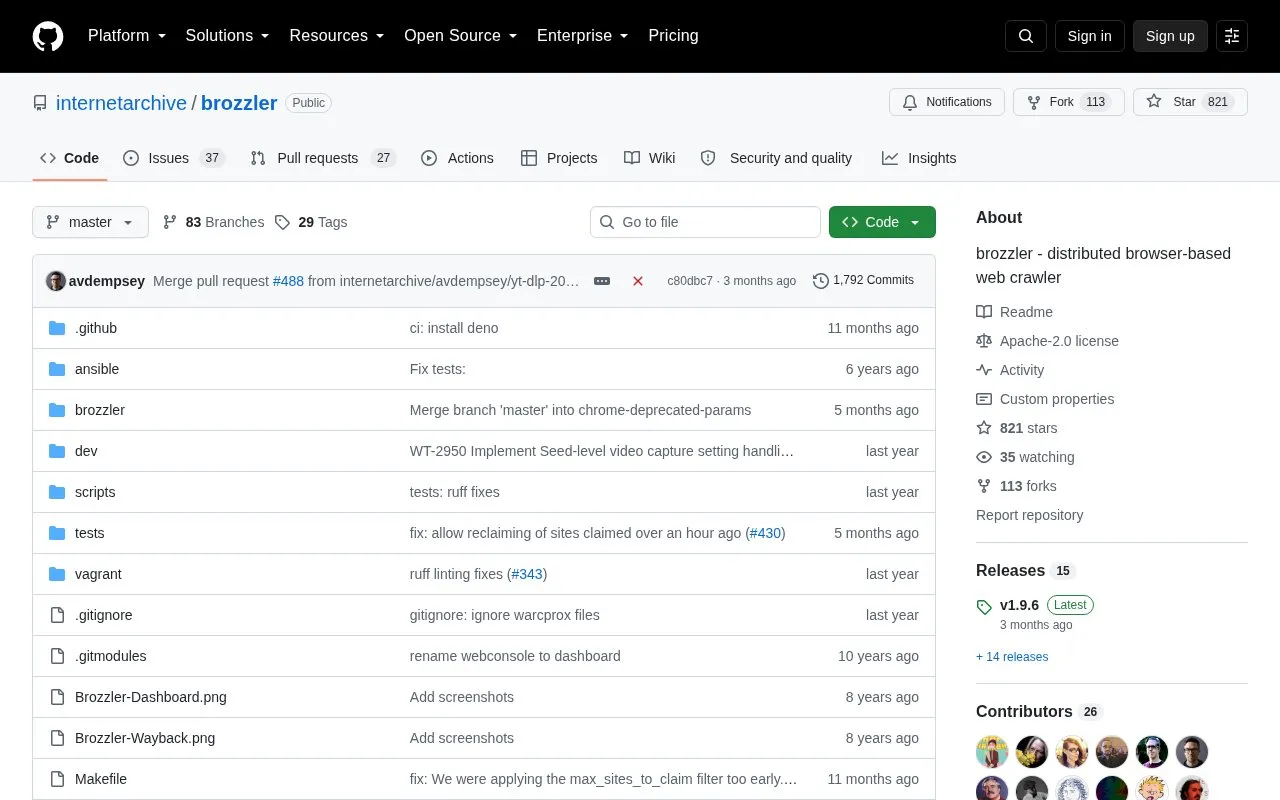
About brozzler
Brozzler is a distributed web crawler that uses Chrome or Chromium to fetch pages, fetch embedded URLs, and extract links. It uses yt-dlp for media capture and RethinkDB to manage crawl state, and is designed to work with warcprox for web archiving.
Jobs are defined in YAML files with seed URLs, and single pages can be crawled with the brozzle-page command. It requires Python 3.9 or later, RethinkDB, Chrome or Chromium 64 or newer, and a graphical environment, with additional setup needed on servers.
Key features
- Crawls pages using real Chrome or Chromium browser
- Fetches embedded URLs and extracts links from pages
- Uses yt-dlp to enhance media capture capabilities
- Manages crawl state with RethinkDB
- Works with warcprox for web archiving
- Defines crawl jobs with YAML seed files
Best for: Developers and archivists building browser-based crawls for web archiving.
Good for
- Uses a real browser to fetch pages and extract links
- Supports distributed crawling with multiple workers
- Includes YAML job configuration and job-status dashboard
Watch out for
- Requires Python 3.9+, RethinkDB, and Chrome or Chromium 64+
- Needs graphical environment or X11 setup such as Xvnc4 on servers
- Dashboard is described as rudimentary
brozzler at a glance
- Category
- Development › Developer Tools
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Open source
- Yes · Source code
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
Guides for Developer Tools
brozzler alternatives
Tools and sites you could use instead, ranked by how closely they match.

Heritrix is the Internet Archive’s open-source, extensible web crawler for archival collection.

Collect and structure website data with Octoparse, a no-code web scraping tool.

Download an entire website from the Internet Archive Wayback Machine with this Ruby command-line tool.
Pick
24 alternatives
Awesome CLI provides a command-line tool for browsing and exploring Awesome lists.
Open sourcePick
24 alternatives
Claude Usage Tracker is a browser extension for viewing Claude usage information.
Open source
24 alternatives
Share terminal sessions in a browser with sshx, including chat and movable windows on a collaborative canvas.
Open source
24 alternativesPopular in Developer Tools
Well-known listings from the same topic.
AppDevToolsappdevtools.comCommand Not Foundcommand-not-found.comTestFlighttestflight.apple.com/join/A8GwCnq8Sourcegraphabout.sourcegraph.comProject Wallaceprojectwallace.comCarbon Calculatorwebsitecarbon.com


brozzler FAQ
What do I need to run Brozzler?
Python 3.9 or later, a RethinkDB deployment, and Chromium or Google Chrome 64 or newer, plus a graphical environment.
How do I crawl a single page?
Use the brozzle-page command with a URL, for example brozzle-page https://example.org.
How do I check crawl job status?
Install with pip install brozzler[dashboard] and run brozzler-dashboard, then open http://localhost:8000/.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.