
Heritrix3
Heritrix is the Internet Archive’s open-source, extensible web crawler for archival collection.
About Heritrix3
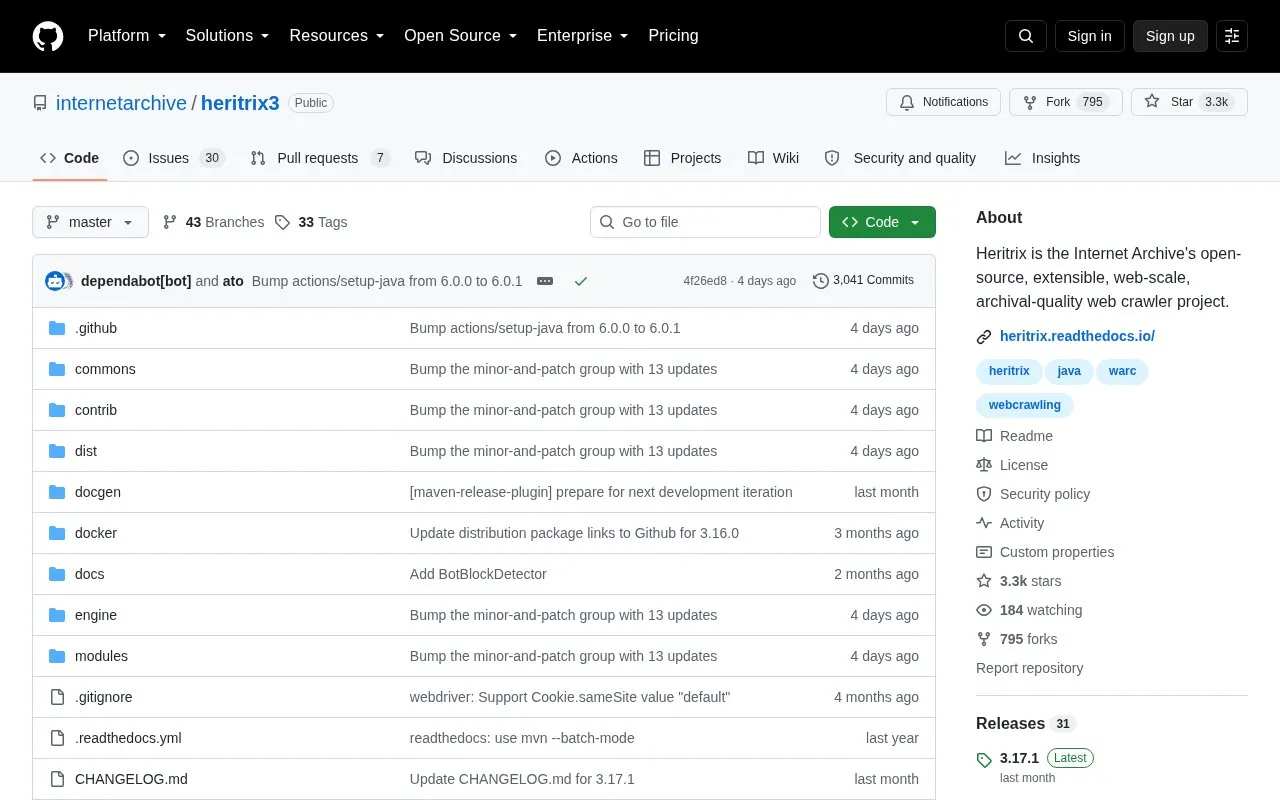
Heritrix is the Internet Archive's open-source, extensible web crawler for archival collection of web content. It is intended for web-scale crawling and supports configuration of crawl jobs.
It respects robots.txt exclusion directives and META nofollow tags. Operators are expected to set politeness policies to limit load on seed sites and to identify crawls with contact information in the User-Agent.
Key features
- Collects web content for archival preservation
- Extensible design for web-scale crawling
- Respects robots.txt exclusion directives
- Respects META nofollow tags
- Configurable politeness policies for seed sites
- Configurable User-Agent with contact information
Best for: Crawl operators and developers who need an extensible crawler for archival web collections.
Good for
- Free software available under Apache License, Version 2.0
- Extensible design intended for web-scale archival crawling
- Respects robots.txt and META nofollow tags
Watch out for
- Does not crawl content disallowed by robots.txt or META nofollow tags
- Requires operators to set politeness policies to limit load on seed sites
Heritrix3 at a glance
- Category
- Development › Developer Tools
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Open source
- Not stated
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
Guides for Developer Tools
Heritrix3 alternatives
Tools and sites you could use instead, ranked by how closely they match.

Brozzler crawls the web through a distributed browser-based crawler project from the Internet Archive.
Open source
24 alternatives
Collect and structure website data with Octoparse, a no-code web scraping tool.

Download an entire website from the Internet Archive Wayback Machine with this Ruby command-line tool.
Pick
24 alternativesHeritrix 3 documentation describes configuration and use of the Heritrix web crawler.

The Cerberus library validates data in Python with a lightweight and extensible design.
Open source
24 alternatives
Awesome CLI provides a command-line tool for browsing and exploring Awesome lists.
Open sourcePick
24 alternativesPopular in Developer Tools
Well-known listings from the same topic.
AppDevToolsappdevtools.comCommand Not Foundcommand-not-found.comTestFlighttestflight.apple.com/join/A8GwCnq8Sourcegraphabout.sourcegraph.comProject Wallaceprojectwallace.comCarbon Calculatorwebsitecarbon.com


Heritrix3 FAQ
What license does Heritrix use?
Heritrix is free software under the Apache License, Version 2.0. Some individual files are under other licenses described in the included LICENSE file.
Does Heritrix respect robots.txt?
Yes, it is designed to respect robots.txt exclusion directives and META nofollow tags.
What are operators asked to do when crawling?
Consider the load on seed sites, set politeness policies accordingly, and identify the crawl with contact information in the User-Agent.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.