

Deploy generative and predictive AI models on Kubernetes with KServe’s distributed inference platform.
Open source
21 alternativesKServe provides distributed inference for generative and predictive AI models on Kubernetes.
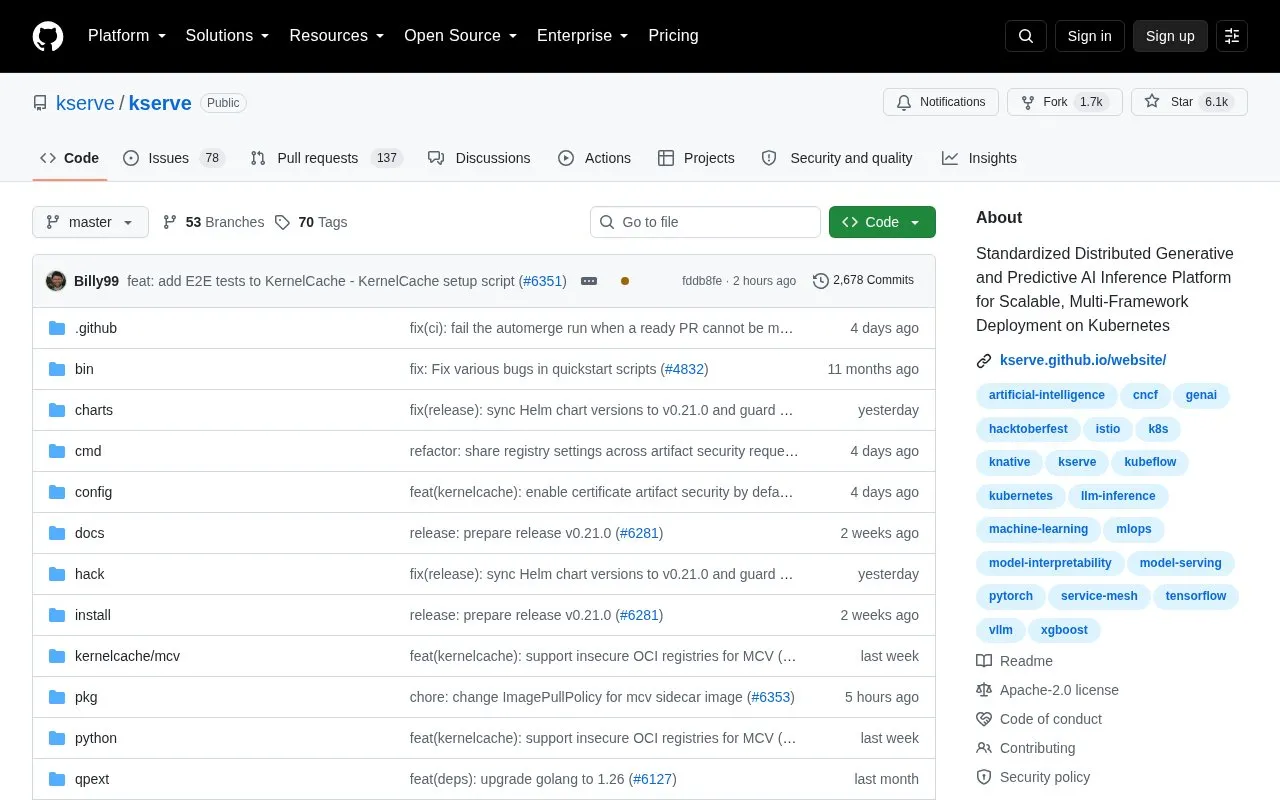
KServe is an open source inference platform for serving generative and predictive AI models on Kubernetes. The repository's homepage describes it as a standardized, distributed platform for scalable deployment across multiple frameworks, and says it is a Cloud Native Computing Foundation (CNCF) incubating project. It covers both large language model serving and traditional machine learning models.
The installation options differ in capability. The standalone standard Kubernetes installation is lighter but does not support canary deployment or request-based autoscaling with scale-to-zero. The default serverless setup installs Knative, which the homepage presents as the option for serverless deployment.
Tools and sites you could use instead, ranked by how closely they match.
Deploy generative and predictive AI models on Kubernetes with KServe’s distributed inference platform.
FedML supports distributed model training, model serving, and federated learning, with a scheduler for AI jobs across cloud and local clusters.
GraphPipe provides a protocol and software for deploying machine learning models separately from their frameworks.
PowerInfer supports serving large language models for local deployment and inference.
NVIDIA Triton Inference Server provides an inference solution for deploying models in cloud and edge environments.
Sonar provides large-scale inference for language models through the project hosted in this repository.
Well-known listings from the same topic.
Tell us and an editor will check it.
Claim the listing and suggest updates yourself. An editor checks every claim first.


