

CTranslate2 provides a C++ and Python inference engine for transformer models.
Open source
21 alternativesLLMKube runs self hosted LLM inference across heterogeneous GPU fleets using Kubernetes and several model runtimes.
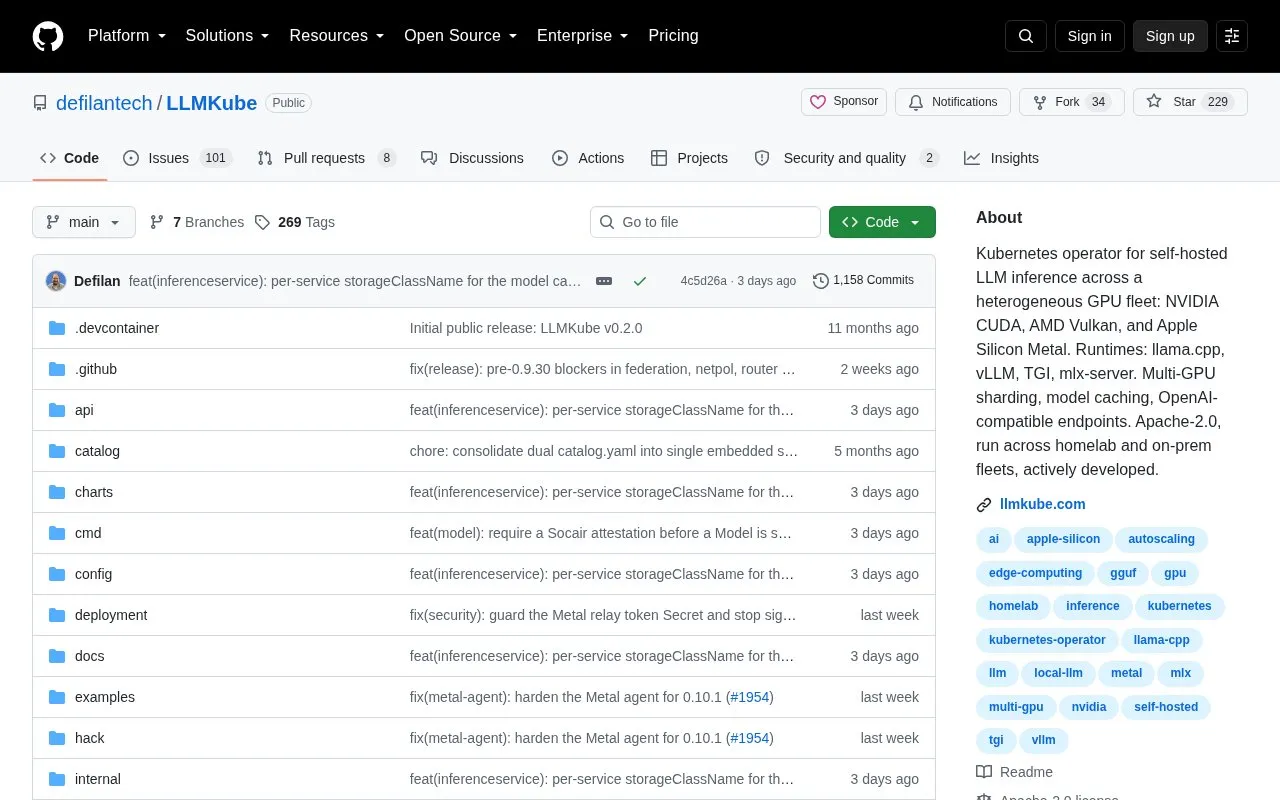
LLMKube is an open-source Kubernetes operator for self-hosted large language model inference. It is designed to run models across a heterogeneous GPU fleet, including NVIDIA CUDA, AMD Vulkan, Apple Silicon Metal, and Intel oneAPI / SYCL hardware. The project is licensed under Apache-2.0 and is intended for homelab and on-premises use.
You define a Model and an InferenceService in YAML, and the operator handles downloading, caching, GPU scheduling, health checks, scaling, and exposing an OpenAI-compatible API. It works with llama.cpp, vLLM, TGI, and mlx-server runtimes, and supports multi-GPU sharding. A ModelRouter component can route requests between local models and external providers such as Anthropic, OpenAI, and LiteLLM.
It suits teams and individuals who need to run LLMs on their own infrastructure for privacy, cost control, or air-gapped compliance. Use requires Kubernetes, with an optional metal-agent process for Apple Silicon hosts.
Tools and sites you could use instead, ranked by how closely they match.
CTranslate2 provides a C++ and Python inference engine for transformer models.
NobodyWho runs language models locally through an inference engine designed for efficient operation across devices.
OpenLLM runs open-source language models as cloud API endpoints compatible with OpenAI clients.
PowerInfer supports serving large language models for local deployment and inference.
GPUStack manages GPU clusters for serving AI models and provides on demand GPU instances accessible through SSH.
Rapid-MLX is an open-source LLM inference server for Apple Silicon, built on MLX, compatible with OpenAI and Anthropic APIs, focused on reliable tool calling for coding agents.
Well-known listings from the same topic.
Tell us and an editor will check it.
Claim the listing and suggest updates yourself. An editor checks every claim first.


