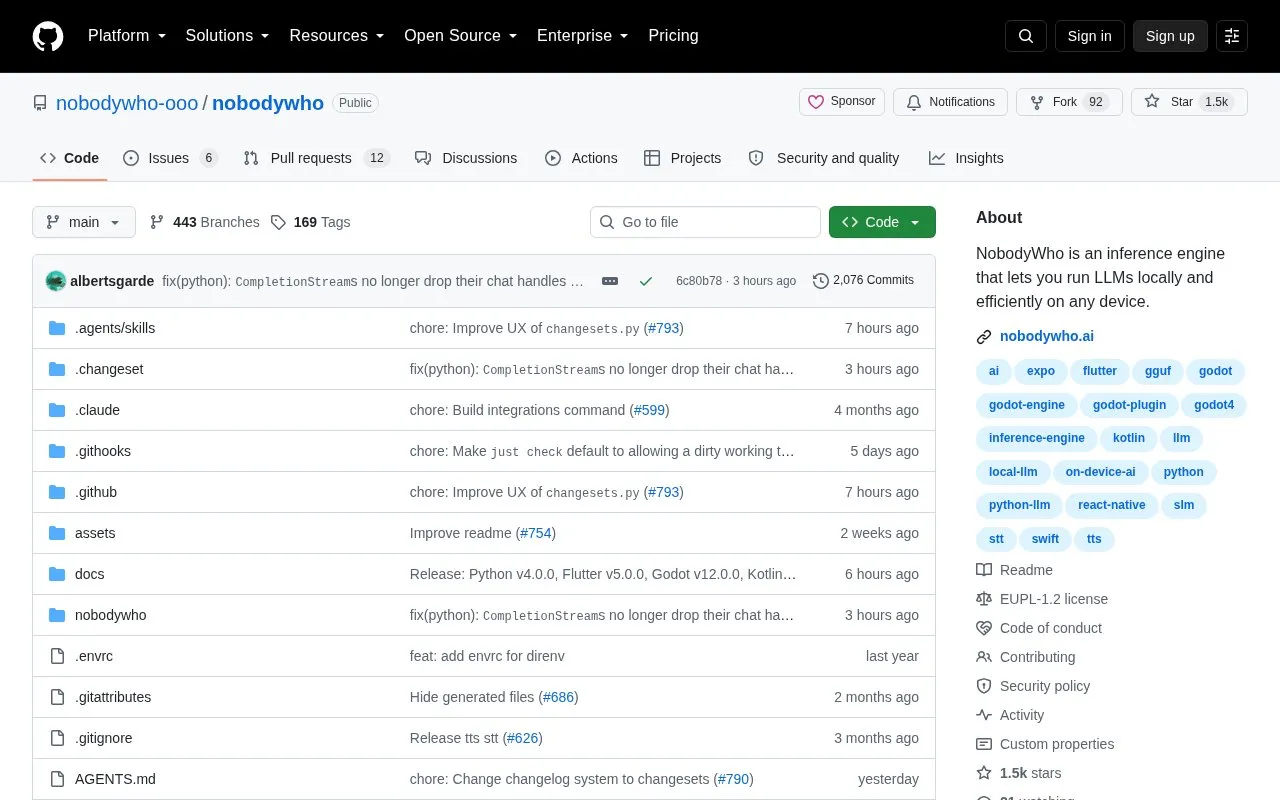
NobodyWho is an open-source inference engine for running large language models (LLMs) locally on a device. It is built on llama.cpp and runs text, vision and embedding models, along with speech-to-text and text-to-speech. The homepage states that it runs offline and needs no API keys. It is available through bindings for Kotlin, Swift, React Native/Expo, Flutter, Python and Godot.
Memory is the main practical limit. The homepage says models need roughly 1.5 times the model file size in free RAM, or about 2 times on a busy machine. Desktop support covers 64-bit Linux, macOS and Windows (x86_64 only). Godot has no iOS export, Windows ARM64 is not supported, and there is no web export.
Key features
Runs LLMs locally with GPU acceleration via Vulkan or Metal, falling back to CPU
Loads GGUF models from Hugging Face or any URL
Tool calling with grammars generated automatically from function signatures
Multimodal input with image and audio information for LLMs
Speech-to-text with Whisper and voice activity detection with Silero
Text-to-speech that synthesizes local WAV audio with Kokoro, Pocket TTS and Supertonic
Best for: Developers who want to run LLMs locally inside desktop or mobile apps, or in Python projects, without relying on an external API.
Good for
Runs locally and offline, and the homepage states that no API keys are needed
Uses GPU acceleration through Vulkan or Metal when available, with CPU fallback
Open source, with a public repository on GitHub
Watch out for
Needs roughly 1.5 times the model file size in free RAM, or about 2 times on a busy machine
Godot has no iOS export, Windows ARM64 is not supported, and there is no web export (tracked in issue #111)
On discrete GPUs, models larger than VRAM still run but more slowly, with remaining layers on CPU
Rapid-MLX is an open-source LLM inference server for Apple Silicon, built on MLX, compatible with OpenAI and Anthropic APIs, focused on reliable tool calling for coding agents.
Desktop means 64-bit Linux, macOS and Windows (x86_64 only). Bindings are listed for Kotlin (desktop, Android), Swift (macOS, iOS, visionOS, watchOS), React Native/Expo (desktop, Android, iOS), Flutter (desktop, Android, iOS), Python (desktop) and Godot (desktop, Android).
How much memory does a model need?
The homepage says roughly 1.5 times the model file in free RAM, or 2 times on a machine that is already busy. An 8 GB machine is described as a comfortable floor for models up to about 2 GB, and 16 GB or more for larger models.
What happens if a model is larger than the GPU's memory?
NobodyWho offloads as many layers as fit in free VRAM and runs the rest on the CPU. The model still works but runs more slowly. If very little fits, it skips the GPU and runs on CPU.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim the listing and suggest updates yourself. An editor checks every claim first.