ANEE

ANEE wraps pretrained transformer inference with an energy budget and early exits inside model execution.

github.com/abkmystery/ANEE
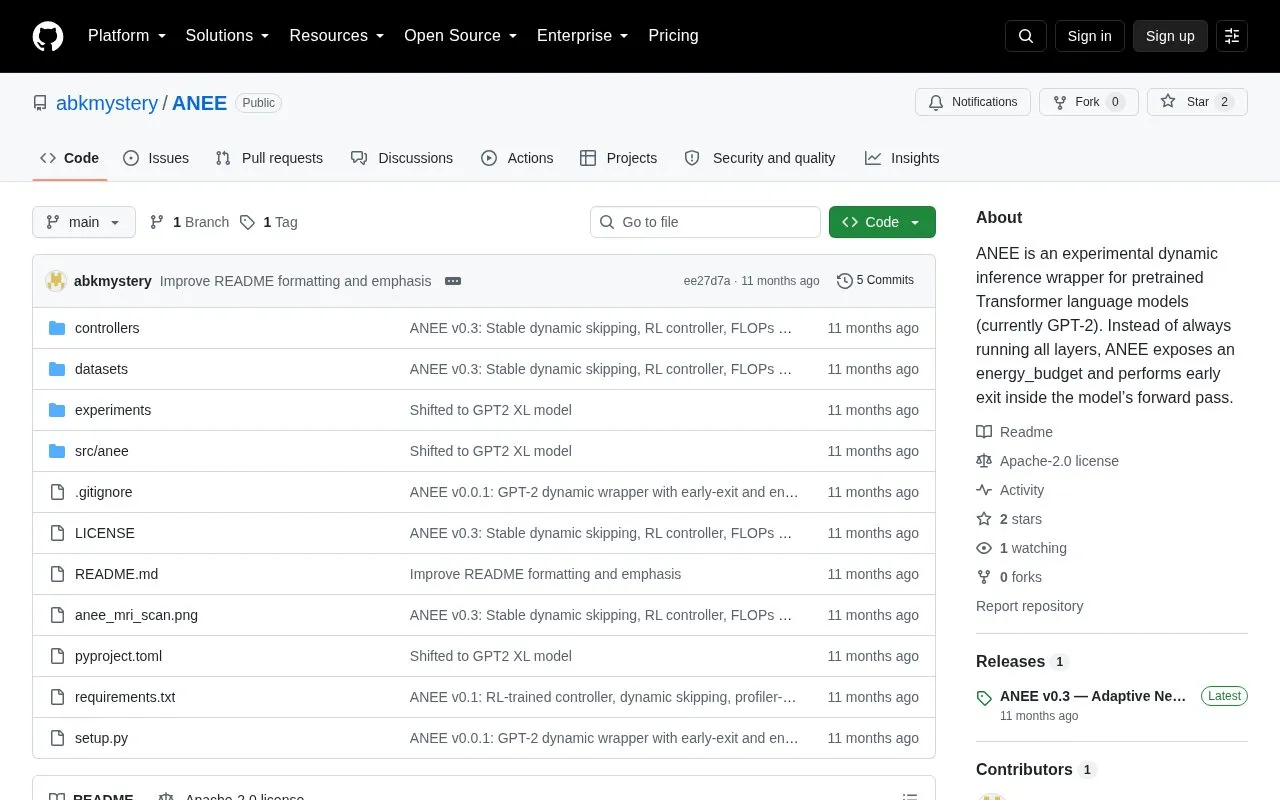
ANEE homepage screenshot

About ANEE

ANEE is an experimental Python wrapper for pretrained autoregressive Transformer models with full support for the GPT-2 family. It adds per-token adaptive computation inside the forward pass, using an energy_budget setting and a profiler-driven controller to decide whether to run a full layer, update only the KV-cache, or exit early.

It has been tested on GPT-2 small, medium, large, and XL, with reported 50–55% theoretical FLOPs savings on large models at low budgets. Adapters for GPT-J, LLaMA, Falcon, and Mistral are listed as planned, not yet supported.

Key features

  • Per-token layer skipping controlled by energy_budget setting
  • Profiler builds state from entropy, norms, variance, and budget
  • Skipped layers update KV-cache keys and values only
  • Choice of heuristic controller or REINFORCE-trained controller
  • Model adapters with full support for GPT-2 sizes
  • Per-layer PROCESS, SKIP, and optional EXIT decisions
Best for: Researchers experimenting with per-token adaptive inference on GPT-2 models.
Good for
  • Reported 53-55% theoretical FLOPs savings on GPT-2-XL at 0.2 budget
  • Maintains KV-cache alignment when layers are skipped
  • Open source under Apache 2.0 license
Watch out for
  • Experimental status for research use
  • Full support limited to GPT-2 family; other adapters planned
  • Reported savings are theoretical FLOPs estimates

ANEE at a glance

Type
Open-source project
Pricing
Not confirmed. Check the site
Open source
Yes · Source code
Language
English
Last checked
Oct 6, 2026 · Online when checked
Listed
Oct 5, 2026

ANEE alternatives

Tools and sites you could use instead, ranked by how closely they match.

All 21 alternatives

Popular in Model Serving & Inference

Well-known listings from the same topic.

All 26

ANEE FAQ

Which models does ANEE support?
GPT-2 family in all sizes has full support. GPT-J, LLaMA, Mistral, and Falcon adapters are listed as planned.
How is ANEE installed and used?
Install with pip install anee, then configure with ANEEConfig and wrap the model with ANEEWrapper to generate text.
What is the reported GPT-2-XL savings example?
At budget 0.2, about 19-21 of 48 layers are executed per token and 28-29 skipped, for 53-55% theoretical savings.
Is something wrong or out of date?

Tell us and an editor will check it.

Own this website?

Claim the listing and suggest updates yourself. An editor checks every claim first.

Claim this listing