

OpenLLM runs open-source language models as cloud API endpoints compatible with OpenAI clients.
Open source
21 alternativesFor Apple Silicon, Rapid-MLX offers an open-source LLM inference server and Mac app compatible with OpenAI and Anthropic APIs.
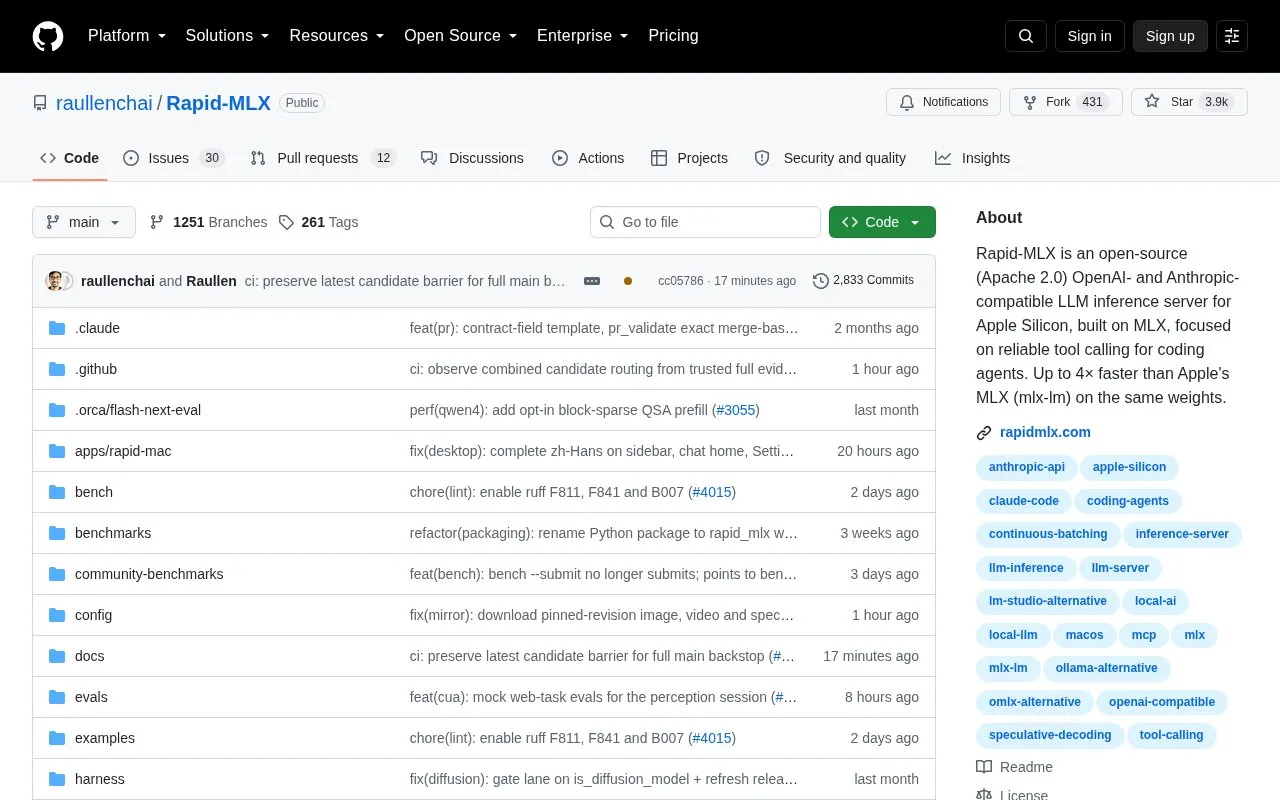
Rapid-MLX is an Apache-2.0 licensed LLM inference server built on MLX for Apple Silicon, with a macOS desktop app. It provides OpenAI-compatible chat completions and responses endpoints and an Anthropic-compatible Messages endpoint, with tool-call parsing for coding agents.
It uses continuous batching, a radix prefix cache saved to disk on shutdown and restored at startup, and speculative decoding. In the project's stated test with Qwen3.5-9B 4-bit on a 48 GB M4 Pro Mac mini, decode results versus mlx-lm ranged from 1.28x to 4.27x with a 1.50x median, and one long-prompt agent turn was 1.05x.
Tools and sites you could use instead, ranked by how closely they match.
OpenLLM runs open-source language models as cloud API endpoints compatible with OpenAI clients.
NobodyWho runs language models locally through an inference engine designed for efficient operation across devices.
GPUStack manages GPU clusters for serving AI models and provides on demand GPU instances accessible through SSH.
LLMKube runs self hosted LLM inference across heterogeneous GPU fleets using Kubernetes and several model runtimes.
PowerInfer supports serving large language models for local deployment and inference.
NVIDIA Triton Inference Server provides an inference solution for deploying models in cloud and edge environments.
Well-known listings from the same topic.
Tell us and an editor will check it.
Claim the listing and suggest updates yourself. An editor checks every claim first.


