

Jina Serve helps developers build multimodal AI applications with cloud-native tools.
Open source
21 alternativesNVIDIA Triton Inference Server provides an inference solution for deploying models in cloud and edge environments.
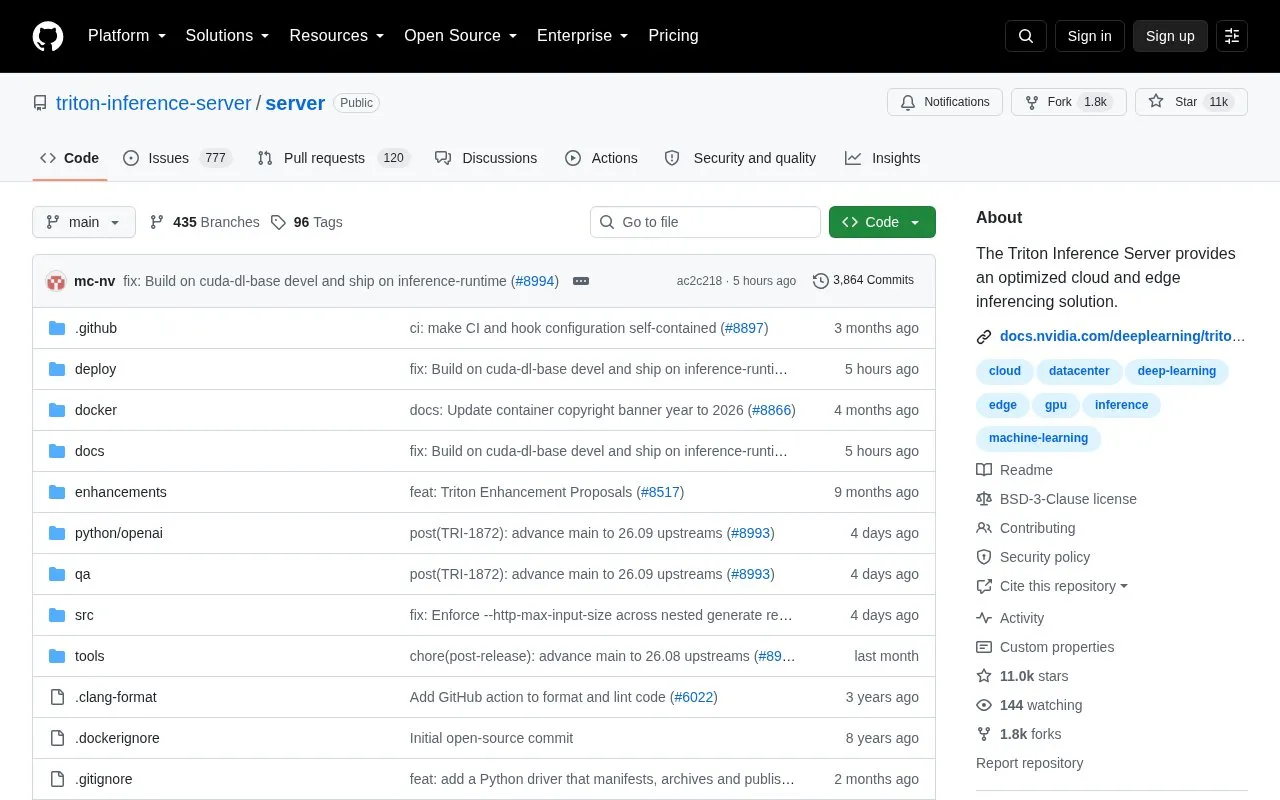
Triton Inference Server is open source inference serving software for deploying AI models across cloud, data center, edge and embedded devices. It serves models from frameworks including TensorRT, PyTorch, ONNX, OpenVINO, Python and RAPIDS FIL on NVIDIA GPUs, x86 and ARM CPUs, and AWS Inferentia. It handles real-time, batched, ensemble and audio/video streaming queries. Deployment uses Docker containers with a model repository, and enterprise support is available through NVIDIA AI Enterprise.
Pricing is not clearly stated.
Tools and sites you could use instead, ranked by how closely they match.
Jina Serve helps developers build multimodal AI applications with cloud-native tools.
Sonar provides large-scale inference for language models through the project hosted in this repository.
GPUStack manages GPU clusters for serving AI models and provides on demand GPU instances accessible through SSH.
Deploy generative and predictive AI models on Kubernetes with KServe’s distributed inference platform.
FedML supports distributed model training, model serving, and federated learning, with a scheduler for AI jobs across cloud and local clusters.
A Rust inference engine for GGUF models, Shimmy uses WebGPU and supports the OpenAI API.
Well-known listings from the same topic.
Tell us and an editor will check it.
Claim the listing and suggest updates yourself. An editor checks every claim first.


