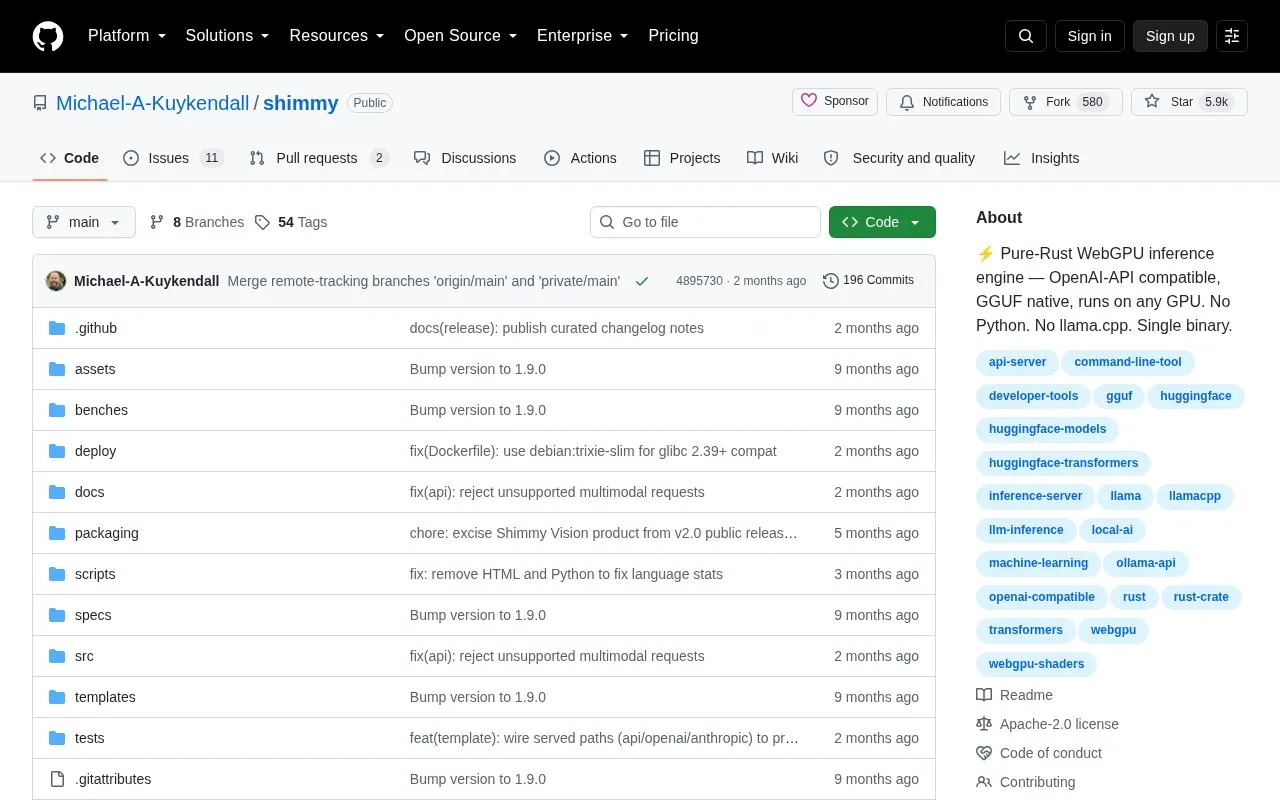
Shimmy is a single-binary, Rust-based inference server for GGUF models with an OpenAI-compatible API for chat completions, text completions, streaming, and model endpoints. It runs on the Airframe WebGPU engine and loads GGUF files as-is, deriving model settings from file metadata.
It lists 26 certified model/quant combinations across 12 families, with certification applying only to the named combination. SafeTensors loading is supported, but full Airframe-native SafeTensors inference and Mixture-of-Experts CPU offloading are described as roadmap work.
Key features
Single-binary inference server for GGUF models
OpenAI-compatible chat, text, streaming and model endpoints
WebGPU execution on NVIDIA, AMD, Intel and Apple Silicon
YaRN RoPE scaling for extended context via SHIMMY_MAX_CTX
INT4 KV cache to reduce KV-cache memory in tested configurations
Deterministic output for same model, seed and parameters
Best for: Developers who want to run supported GGUF models locally using existing OpenAI-compatible tools.
Good for
No Python runtime or C++ toolchain required
Supports varied GPUs including integrated graphics and Apple Silicon via WebGPU
Publishes a defined certification regimen and list of certified model/quant combinations
Watch out for
Certification applies only to named model/quant combinations, not full architectures
Full Airframe-native SafeTensors inference is still roadmap work
Mixture-of-Experts CPU offloading is listed as roadmap work
12 families and 26 certified model/quant combinations. Certification applies to the named model/quant combination, not automatically to all models of an architecture.
Does Shimmy work with OpenAI SDKs and tools?
It provides chat completions, text completions, streaming, and model endpoints for tools that use that API surface.
Does Shimmy support SafeTensors models?
Model loading via safetensors_native is supported, but full Airframe-native inference for SafeTensors remains roadmap work.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim the listing and suggest updates yourself. An editor checks every claim first.