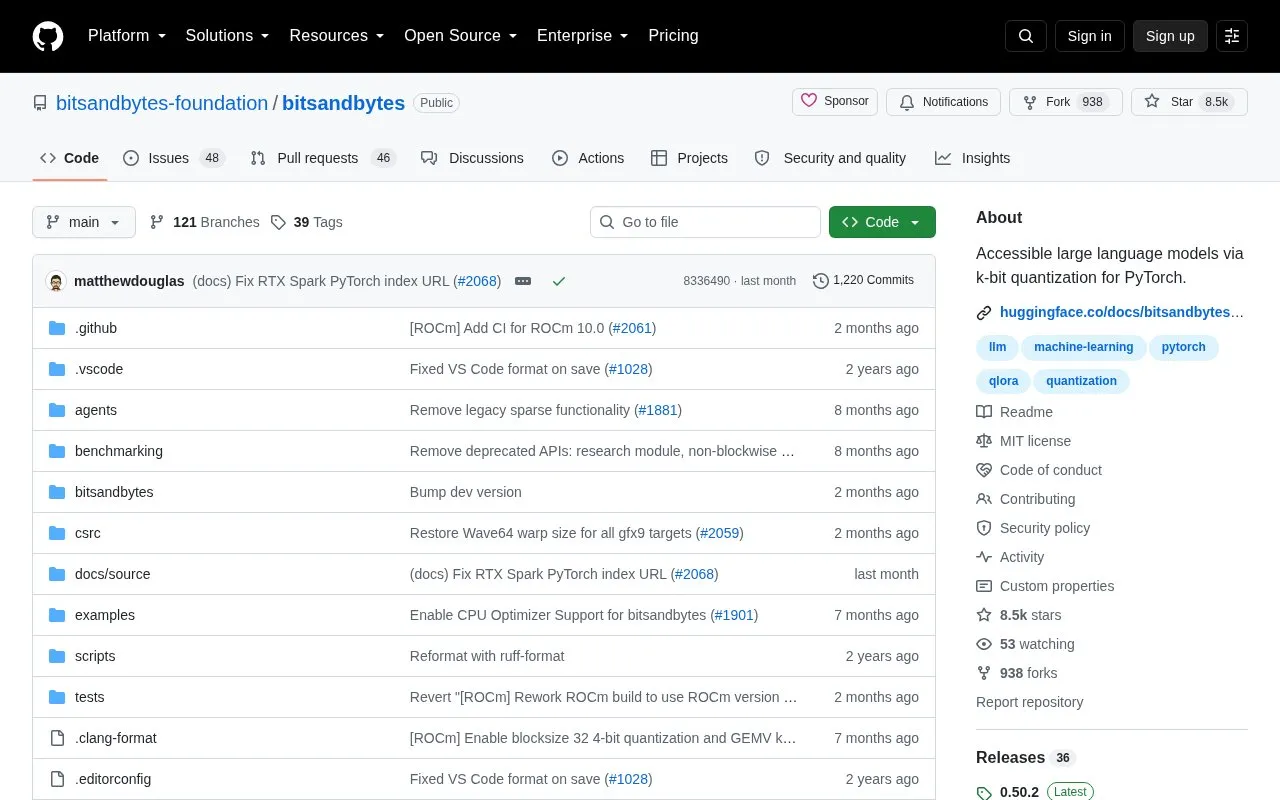
bitsandbytes is an open-source library that enables large language models in PyTorch through k-bit quantization. It offers three main features to reduce memory consumption for inference and training: 8-bit optimizers with block-wise quantization, LLM.int8() for 8-bit inference, and QLoRA for 4-bit training. It also provides quantization primitives such as Linear8bitLt and Linear4bit, plus an 8-bit optim module.
Key features
8-bit optimizers use block-wise quantization to reduce memory while maintaining 32-bit performance.
LLM.int8() enables 8-bit LLM inference with half the required memory, without performance degradation.
QLoRA quantizes models to 4-bit and adds trainable low-rank adaptation (LoRA) weights for training.
Provides quantization primitives: Linear8bitLt, Linear4bit, and an 8-bit optim module.
Supports CPU, NVIDIA, AMD, Intel GPUs and Intel Gaudi accelerators across Linux, Windows, macOS.
Requires Python 3.10+ and PyTorch 2.4+ for all platforms.
Best for: Developers and researchers using PyTorch who need to reduce memory for large language model inference or training.
Good for
Open source under the MIT license.
Reduces memory consumption for inference and training through quantization.
Supports a range of accelerators including CPU, NVIDIA GPU, AMD GPU, Intel GPU, and Intel Gaudi.
Watch out for
Requires Python 3.10+ and PyTorch 2.4+.
Some supported features may lack performance optimizations.
On Intel Gaudi, QLoRA is partially supported and 8-bit optimizers are not supported; on macOS Metal, 8-bit optimizers are planned.