
OCRmyPDF
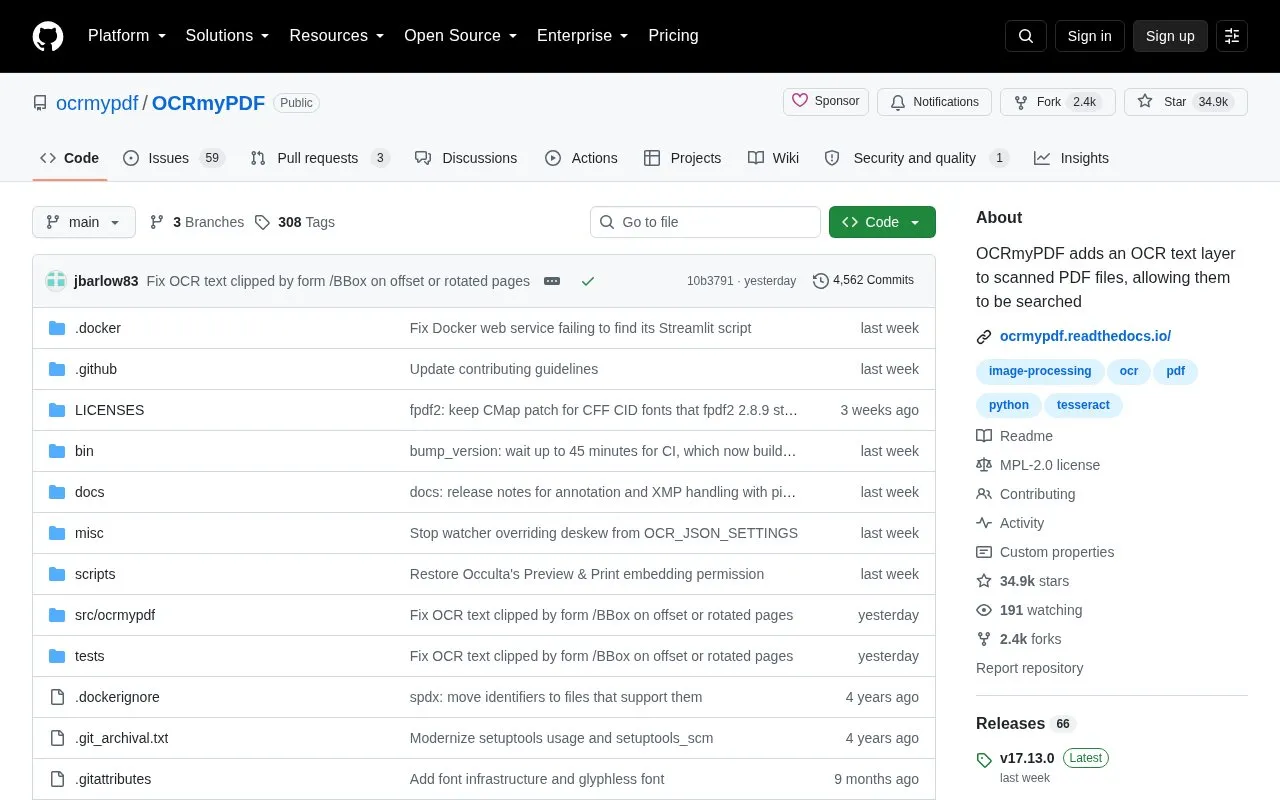
OCRmyPDF adds an OCR text layer to scanned PDF files, making their text searchable, according to its project description.
About OCRmyPDF
OCRmyPDF is an open-source command-line program that adds an OCR text layer to scanned or image-based PDF files so the text can be searched or copied and pasted. It uses the Tesseract OCR engine and produces PDF/A output by default, keeping the resolution of the original embedded images and inserting OCR information as a lossless operation where possible. It can also rotate misrotated pages, deskew crooked scans, change output metadata, and distribute work across available CPU cores.
Installation is documented for Linux, Windows, macOS, FreeBSD, OpenBSD and Ubuntu Snap, and Docker images are published for x64 and ARM. OCRmyPDF requires Tesseract 4.1.1 or later and relies on separately installed Tesseract language packs for the languages it recognizes. It is a scriptable tool, used from the command line or from scripts.
Key features
- Adds a searchable OCR text layer to scanned PDF files
- Produces validated PDF/A output by default
- Rotates misrotated pages and deskews crooked scans
- Keeps original embedded image resolution; optimization can reduce file size
- Recognizes more than 100 languages via Tesseract language packs
- Distributes OCR work across all available CPU cores
Best for: Users comfortable with the command line who need to make scanned or image-based PDFs searchable, including large multi-thousand-page files.
Good for
- Open source, with the full repository publicly available
- Validates input and output files and emits PDF/A by default
- Runs on Linux, Windows, macOS, FreeBSD and OpenBSD, plus x64 and ARM Docker images
Watch out for
- Used as a command-line program; no graphical interface is described
- Requires Tesseract 4.1.1 or later
- Language support depends on which Tesseract language packs are installed separately
OCRmyPDF at a glance
- Website
- github.com/ocrmypdf/OCRmyPDF
- Category
- Online Tools › PDF & Document Tools
- Type
- Open-source project
- Pricing
- Not confirmed. Check the site
- Open source
- Yes · Source code
- Language
- English
- Last checked
- Oct 5, 2026 · Online when checked
- Listed
- Oct 5, 2026
Guides for PDF & Document Tools
OCRmyPDF alternatives
Tools and sites you could use instead, ranked by how closely they match.

The Stirling PDF project describes an editing application that can run on infrastructure selected by the user.
Search PDF text from the command line with pdfgrep, which supports GNU grep-style options such as recursive and case-insensitive search.

This repository contains plugins for Umi-OCR, including components that add OCR engines.
Open sourcePick
10 alternatives
PDFCraft describes a browser-based toolkit for editing, converting, merging, splitting, and securing PDF files.
FreeOpen source
18 alternatives
Signaturepdf is open-source web software for signing PDFs, organizing pages, editing metadata, and compressing files.
Open source
14 alternatives
Convert PDF files into Markdown and JSON with Marker, a Python project described by its maintainers as fast and accurate.
Open source
12 alternativesPopular in PDF & Document Tools
Well-known listings from the same topic.
2OCR2ocr.com2PDFConverter2pdfconverter.comBentopdfgithub.com/alam00000/bentopdfOCRToolocrtool.netPDFCoffeepdfcoffee.comPDF24pdf24.org


OCRmyPDF FAQ
What kind of output does OCRmyPDF produce?
It produces a searchable PDF file, with PDF/A as the default output type; the output type can be changed with a command-line option.
How do I select the OCR language?
Pass the -l argument with one or more language codes, for example -l eng+fra. The corresponding Tesseract language packs must be installed first.
Which operating systems are supported?
Linux, Windows, macOS, FreeBSD and OpenBSD, with package commands listed for Debian/Ubuntu, Fedora, Homebrew, MacPorts, nix, LinuxBrew, FreeBSD, OpenBSD and Ubuntu Snap. Docker images are also available for x64 and ARM.
Is something wrong or out of date?
Tell us and an editor will check it.
Own this website?
Claim this listing
Claim the listing and suggest updates yourself. An editor checks every claim first.